



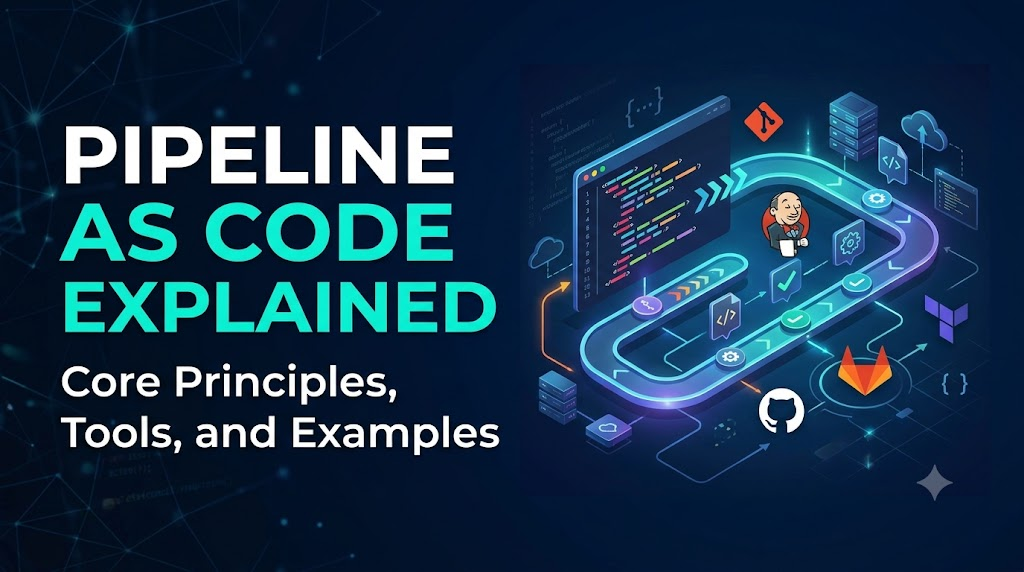
Manual build configurations and unversioned server settings often turn software delivery into an unpredictable, error-prone bottleneck. What Is Pipeline as Code? It is the DevOps practice of defining your build, test, security, and deployment workflows entirely in version-controlled text files stored alongside your application code. By replacing fragile, click-driven setup menus with reviewable, automated code, teams gain complete visibility, repeatability, and confidence across every stage of the modern CI/CD lifecycle.
Defining Pipeline as Code
At its core, Pipeline as Code in DevOps means your Continuous Integration and Continuous Delivery (CI/CD) workflows are expressed as machine-readable text files stored in a version control system like Git.
A pipeline definition file serves as the single source of truth for the delivery lifecycle. Depending on your tooling and operational needs, these files define:
- Triggers: What events run the pipeline (such as a pull request, a push to a main branch, a git tag, or a scheduled cron).
- Execution Stages: The logical phases of delivery, such as linting, building, testing, security scanning, packaging, and deploying.
- Job Dependencies: Which tasks run concurrently to save time and which must wait for upstream prerequisites.
- Execution Environments: The specific container images, operating systems, or virtual machine agents required to run each job.
- Environment Variables and Parameters: Configuration settings required for builds across environments.
- Artifact Management: Instructions for generating, packaging, and storing binaries, test reports, or container images.
- Security and Quality Gates: Automated vulnerability scanners, code coverage checks, or compliance verifications.
- Approval Gates: Manual reviews required before deploying to sensitive environments like staging or production.
- Failure Handling and Alerts: Clean-up routines, retries, and notifications sent via webhooks or chat platforms if a step fails.
While YAML is the most widely adopted format across modern CI/CD engines, Pipeline as Code is not restricted to YAML. Some platforms use domain-specific languages (DSLs) like Groovy, while others allow engineers to write pipelines using general-purpose programming languages like TypeScript, Python, or Go.
How Pipeline as Code Works
To understand how CI/CD Pipeline as Code operates in production, let’s trace the lifecycle of a code change from a developer’s machine to an environment.
+-----------------------------------------------------------------------------------+
| 1. Developer pushes commit or opens Pull Request (with application code & pipeline)|
+------------------------------------------+----------------------------------------+
                                           |
                                           v
+-----------------------------------------------------------------------------------+
| 2. CI/CD Platform parses pipeline file, schedules isolated runner/agent           |
+------------------------------------------+----------------------------------------+
                                           |
                                           v
+-----------------------------------------------------------------------------------+
| 3. Execution: Lint -> Unit Tests -> Build -> Security Scans -> Artifact Creation  |
+------------------------------------------+----------------------------------------+
                                           |
                                           v
+-----------------------------------------------------------------------------------+
| 4. Conditional Gate: Passed? -> Trigger Deploy | Failed? -> Halt & Notify Team    |
+-----------------------------------------------------------------------------------+
The Delivery Lifecycle Step-by-Step
- Authoring or Updating: An engineer edits the pipeline file (for example,
.github/workflows/deploy.ymlor aJenkinsfile) directly in their local editor alongside feature code. - Commit and Push: The change is committed and pushed to the remote Git repository.
- Event Ingestion: The Git host or CI/CD platform intercepts the webhook event (such as
pushorpull_request). - Parsing and Graph Generation: The CI/CD engine reads the pipeline definition, parses its syntax, and resolves it into a Directed Acyclic Graph (DAG) that maps out sequential and parallel jobs.
- Agent Allocation: The platform requests or provisions runners (compute agents) matching the pipeline’s environmental requirements (such as Ubuntu with Docker installed).
- Task Execution: The runner checks out the repository, sets up environment variables, and executes the specified shell commands, scripts, or container tasks.
- Artifact and Report Collection: Outputs—such as compiled binaries, container images, or code coverage reports—are uploaded to an artifact registry or pipeline storage.
- Conditional Evaluation: The system evaluates exit codes. If unit tests fail, the workflow stops immediately to prevent broken code from proceeding.
- Deployment and Governance: If all stages pass, downstream deployment jobs execute, potentially waiting for an environment-level approval check.
- Feedback and Logging: Complete execution logs, metrics, and statuses are attached to the Git commit or pull request, giving developers clear, immediate feedback.
Key Architectural Concepts
- Triggers: The specific events that initiate pipeline execution.
- Stages: Logical groups of jobs (e.g.,
Build,Test,Release). - Jobs: A collection of steps executed on the same runner instance.
- Steps: Individual tasks or shell commands executed sequentially within a job.
- Runners/Agents: Ephemeral or persistent compute instances that perform the actual work.
- Artifacts: Files or binaries created by a job that need to persist after the runner shuts down.
- Environments: Target deployment targets (e.g.,
staging,production) paired with specific access policies and protection rules.
Pipeline as Code vs. Traditional Pipeline Configuration
Traditional CI/CD relied heavily on “ClickOps”—configuring build jobs by manually navigating web administrative consoles. While convenient for quick tests, this approach collapses under the demands of modern engineering teams.
| Feature / Dimension | Traditional Web-UI Configuration | Pipeline as Code |
| Configuration Creation | Manual forms, text boxes, and checkboxes in a web UI | Plain text or code written in text editors |
| Storage Location | Internal database of the CI/CD server | Git repository alongside application source code |
| Version Control | None, or limited to platform-specific UI audit logs | Full Git history: commits, tags, branches, and diffs |
| Code Review | Difficult or impossible; changes happen live | Standard Pull Request / Merge Request review workflows |
| Reproducibility | Low; hard to recreate exact settings on new servers | High; fully reproducible anywhere the engine runs |
| Change Tracking | Unclear who changed what flag or environment variable | Clear commit authorship showing exactly who changed what |
| Branch Awareness | Static; usually tied to one branch or requires duplicate jobs | Dynamic; pipelines branch and merge with application code |
| Testing Pipeline Changes | Tested directly in production, risking broken builds | Tested safely on feature branches before merging |
| Disaster Recovery | Requires restoring complex database backups | Re-apply the repository file to any compatible runner |
| Maintenance at Scale | Exponentially painful as job counts grow | Manageable through templates, shared libraries, and linting |
Relying on manual UI configuration creates undocumented tribal knowledge. If an administrator leaves the organization, teams are often afraid to touch working pipelines. Storing your pipeline as code treats configuration with the same rigor as product features.
Core Principles of Pipeline as Code
Adopting this methodology requires adhering to a few core engineering principles:
1. Version Control Alongside Code
Store your pipeline definition in the same repository as the application code it builds. This guarantees that your build steps evolve atomically with the application. If a developer upgrades a framework version on a branch, they can update the pipeline dependencies on that exact same branch without breaking the main branch build.
2. Peer Review and Auditable Changes
Every change to your build and deployment process should pass through the same peer review process as application code. Pull requests allow team members to catch insecure scripts, missing tests, or flawed deployment logic before it hits a live environment.
3. Idempotency and Repeatability
Pipelines should be deterministic. Running the same pipeline definition against the exact same commit hash should produce the exact same build artifact and test results, regardless of when it is executed.
4. Modular and Reusable Logic
Avoid copying and pasting identical 50-line YAML snippets across forty repositories. Use shared templates, reusable workflows, and modular libraries to standardize organizational practices like security scanning and Docker builds.
5. Shift-Left Security and Least Privilege
Pipeline files run arbitrary shell commands on compute instances with network access. Apply strict access controls, use short-lived credentials (like OIDC tokens), and scan pipeline configurations for misconfigurations and exposed secrets.
6. Comprehensive Observability
Every pipeline run must generate clear, readable diagnostic output. Standardized logging, exit codes, and test result reporting ensure that when builds fail, developers can quickly diagnose the root cause without needing administrator access to the underlying runner.
Popular Tools Supporting Pipeline as Code
Different CI/CD platforms support Pipeline as Code through distinct design philosophies, formats, and ecosystems.
GitHub Actions
- Configuration Format: YAML files located in
.github/workflows/. - Architecture: Event-driven architecture where workflows respond to dozens of GitHub webhook events (
push,pull_request,issue_comment,release). Workflows consist of jobs containing reusable composite actions or direct shell steps. - Strengths: Seamless integration with GitHub repositories, a vast marketplace of pre-built community actions, matrix builds, and built-in OpenID Connect (OIDC) support for cloud providers.
- Considerations: Complex workflows can become verbose in YAML; broad use of unpinned third-party marketplace actions introduces supply chain risks.
- Best For: Teams already hosting their code on GitHub seeking deeply integrated CI/CD without managing server infrastructure.
GitLab CI/CD
- Configuration Format: A single
.gitlab-ci.ymlfile located at the repository root. - Architecture: Centered on explicit pipeline stages (e.g.,
build,test,deploy) with automatic dependency tracking, rich caching mechanics, and tightly coupled auto-scaling GitLab Runners. - Strengths: Outstanding out-of-the-box support for microservices via parent-child pipelines, multi-project pipelines, a standardized component catalog, and deep built-in container registry integrations.
- Considerations: Managing large, multi-thousand-line monolithic YAML files requires disciplined use of
include:andextends:tags. - Best For: Organizations looking for an all-in-one DevOps platform with unified source control, CI/CD, issue tracking, and container registries.
Jenkins (Jenkins Pipeline)
- Configuration Format: A
Jenkinsfilewritten in either Declarative or Scripted Groovy syntax. - Architecture: Jenkins Pipeline uses a specialized Groovy DSL. Declarative pipelines offer a structured, opinionated syntax, while Scripted pipelines provide the full programmatic power of Groovy.
- Strengths: Extreme flexibility, thousands of plugins, and proven ability to handle massive enterprise workloads and legacy on-premises infrastructures.
- Considerations: Significant administrative overhead. Requires dedicated maintenance, patching, plugin compatibility management, and Groovy language expertise.
- Best For: Large enterprises with highly complex, non-standard legacy workflows or strict requirements for self-hosted infrastructure.
Azure Pipelines
- Configuration Format: YAML files (e.g.,
azure-pipelines.yml). - Architecture: Structured around stages, jobs, and steps, with dedicated support for deployment jobs, approvals, and managed release environments.
- Strengths: Deep integration with Azure services and enterprise Active Directory, hybrid support for both cloud-hosted and on-premises build agents, and clean separation between build and deployment approvals.
- Considerations: Cross-project template sharing can have a steep learning curve.
- Best For: Enterprise environments with significant investments in Microsoft Azure, Azure DevOps, and .NET ecosystems.
CircleCI
- Configuration Format: YAML files located in
.circleci/config.yml. - Architecture: Focuses heavily on speed, caching, Docker layer caching, and reusable configuration modules called “Orbs.”
- Strengths: Fast execution, powerful parallelism features, and easy-to-use configuration syntax.
- Considerations: Relies heavily on its proprietary configuration structure, meaning less transferable syntax if migrating.
- Best For: Fast-moving engineering teams prioritizing rapid build times and simple containerized test environments.
Tekton
- Configuration Format: Kubernetes Custom Resource Definitions (CRDs) written in YAML.
- Architecture: Tekton is a cloud-native framework that runs directly inside Kubernetes. Pipelines, tasks, and runs are native Kubernetes resources (
Task,Pipeline,TaskRun,PipelineRun). - Strengths: Infinite horizontal scalability, native alignment with container runtimes, and ideal as an engine for building internal developer platforms (IDPs).
- Considerations: Very low-level and verbose. It is an underlying building block rather than a turnkey developer tool.
- Best For: Platform engineering teams building custom, container-native CI/CD solutions on top of Kubernetes.
Practical Pipeline as Code Example
Below is a production-grade, realistic example using GitHub Actions. It demonstrates automated validation, multi-version testing, artifact handling, and safe branch triggers for a Node.js web application.
YAML
name: Continuous Integration & Build

# Trigger the pipeline on pushes to the main branch or on any Pull Request targeting main
on:
  push:
    branches: [ "main" ]
  pull_request:
    branches: [ "main" ]

# Set workflow-level permissions according to the principle of least privilege
permissions:
  contents: read

jobs:
  test:
    name: Run Linters and Unit Tests
    runs-on: ubuntu-latest

    strategy:
      matrix:
        # Verify compatibility across multiple supported runtime versions
        node-version: [18.x, 20.x]

    steps:
      - name: Check out repository source code
        uses: actions/checkout@v4

      - name: Set up Node.js ${{ matrix.node-version }}
        uses: actions/setup-node@v4
        with:
          node-version: ${{ matrix.node-version }}
          # Automatically cache package manager dependencies
          cache: 'npm'

      - name: Install dependencies cleanly
        run: npm ci

      - name: Run code linter
        run: npm run lint

      - name: Execute automated unit test suite
        run: npm test -- --coverage

  build:
    name: Build Application Package
    needs: test # Ensure build only executes if all tests in the matrix succeed
    runs-on: ubuntu-latest

    steps:
      - name: Check out repository source code
        uses: actions/checkout@v4

      - name: Set up Node.js 20.x
        uses: actions/setup-node@v4
        with:
          node-version: 20.x
          cache: 'npm'

      - name: Install dependencies
        run: npm ci

      - name: Compile application assets
        run: npm run build

      - name: Archive build artifacts for deployment
        uses: actions/upload-artifact@v4
        with:
          name: compiled-application-dist
          path: dist/
          retention-days: 7
How This Example Works
- File Location: This file resides in
.github/workflows/ci.ymldirectly in the project repository. - Trigger Mechanism: When a developer pushes a branch or creates a pull request targeting
main, GitHub evaluates this file and schedules the jobs. - Matrix Testing: The
testjob creates two parallel executions—one running on Node.js 18 and another on Node.js 20. If either matrix run fails, the entire job is marked failed. - Failure Isolation: The
buildjob includesneeds: test. If the linter or tests fail, the build job never runs. This prevents teams from compiling or storing broken code. - Artifact Retention: The final step stores the compiled
dist/directory securely in the CI system for 7 days, making it available for a downstream deployment job without recompilation.
Step-by-Step Implementation Guide
Transitioning from manual workflows to version-controlled pipelines works best when treated as an incremental process.
Step 1: Audit Current Workflow
  │
Step 2: Select Tooling
  │
Step 3: Map Architecture & Stages
  │
Step 4: Draft Pipeline Configuration
  │
Step 5: Store in Version Control
  │
Step 6: Validate & Lint
  │
Step 7: Run Parallel Testing
  │
Step 8: Enforce Secrets & Security
  │
Step 9: Configure Deployment Gates
  │
Step 10: Standardize & Refactor
Step 1: Understand and Document the Existing Workflow
Map out what currently happens between writing code and deploying it:
- What shell commands do developers run locally to test?
- What environment variables are required?
- Which manual steps do engineers take when publishing a build?
- Document every step on a whiteboard or design doc before writing any YAML.
Step 2: Select a Suitable CI/CD Platform
Choose a tool that aligns with your infrastructure and source control. If you use GitLab, start with .gitlab-ci.yml. If your code is on GitHub, GitHub Actions is the natural starting point. Avoid selecting a tool that requires managing dedicated servers unless your security or compliance posture demands it.
Step 3: Define the Pipeline Structure
Decide on your stages, job boundaries, and execution order. A standard baseline is:Lint $\rightarrow$ Test $\rightarrow$ Build $\rightarrow$ Security Scan $\rightarrow$ Deploy to Staging $\rightarrow$ Manual Approval $\rightarrow$ Deploy to Production.
Step 4: Create the Initial Pipeline Definition
Start small. Do not try to automate your production release on day one. Write a pipeline definition that only checks out the code and runs the unit test suite on a feature branch.
Step 5: Store It in Version Control
Place the file in your repository’s standard directory (.github/workflows/, .gitlab-ci.yml, or Jenkinsfile). Commit it on a feature branch and open a pull request.
Step 6: Validate and Lint the Definition
Before pushing, run a syntax validator:
- Use tools like
yamllintor platform-specific extensions (like the GitHub Actions or GitLab CI VS Code extensions). - Use CLI validation commands (such as
gitlab-ci-lintoractionlint) to catch syntax errors, missing parameters, and typos.
Step 7: Test the Workflow
Trigger the pipeline. Verify that:
- Jobs run in the expected sequence.
- Dependencies are cached correctly across runs.
- Test failures halt the pipeline as expected (test this intentionally by writing a failing test).
Step 8: Add Security Controls
- Remove all hardcoded passwords, tokens, or private keys.
- Move sensitive credentials to your CI/CD platform’s encrypted secret store or an external secrets manager like HashiCorp Vault, AWS Secrets Manager, or Azure Key Vault.
- Scope job permissions to read-only wherever possible.
Step 9: Introduce Deployment Controls
Add your deployment stages. Require protected environment rules, such as mandatory approval from senior engineers or platform leads, before any pipeline can execute steps against production environments.
Step 10: Maintain and Refactor
Continuously evaluate pipeline performance. Cache slow package dependencies, prune redundant build steps, and break monolithic pipelines into reusable modules as your team expands.
Security Best Practices for Pipeline as Code
Pipelines have become prime targets for software supply chain attacks. Because CI/CD runners often have administrative network access and deployment privileges, an insecure pipeline configuration can compromise your entire infrastructure.
- Enforce Principle of Least Privilege: Default your pipeline jobs to read-only access. Only grant write or deployment permissions to specific jobs that require them (for example, publishing a package or tagging a release).
- Eliminate Static Secrets with OIDC: Avoid storing long-lived cloud provider credentials (like static AWS Access Keys) in your CI/CD settings. Instead, configure OpenID Connect (OIDC). OIDC allows your pipeline runner to exchange short-lived, cryptographically signed tokens for temporary cloud access roles.
- Pin Actions and Dependencies to Specific Hashes: Never reference mutable tags for third-party actions or shared libraries (e.g.,
uses: third-party/action@v1or@main). If a maintainer’s account is compromised, the tag could point to malicious code. Pin to a full SHA hash:YAML# Secure: Pinned to exact commit SHA uses: actions/checkout@b4ffde65f46336ab88eb53be808477a3936bae11 # v4.1.1 - Isolate Untrusted Pull Requests: Be extremely cautious when running pipelines on pull requests originating from forks or untrusted contributors. Malicious pull requests can modify the pipeline file to print environment variables or exfiltrate secrets during execution.
- Mask Secrets in Logs: Ensure your CI platform automatically masks registered secrets so they never appear in console logs. Add safeguards to prevent developers from accidentally echoing base64-encoded strings or debugging dumps that contain sensitive variables.
- Protect Branches and Pipeline Files: Require code reviews for any pull request that modifies workflow definitions. Use code ownership controls (like
CODEOWNERSfiles) so that changes to CI/CD files must be approved by the DevOps or security team.
Testing, Debugging, and Troubleshooting Pipelines
Unlike application code, debugging pipelines can be frustrating if your only feedback loop is pushing commits and waiting ten minutes for a cloud runner to fail. Understanding common pitfalls and how to troubleshoot them saves hours of trial-and-error.
1. Differentiating Syntax Validation from Semantic Testing
- Syntax Validation: Verifies that your YAML or DSL is structurally valid, indentation is correct, and required keys are present. This does not guarantee the pipeline will execute successfully.
- Semantic and Runtime Testing: Confirms that the environment contains the necessary binaries, that paths exist, that environment variables are populated, and that shell scripts exit with zero.
2. Common Pipeline Failures and How to Fix Them
- YAML Indentation Errors: YAML is indentation-sensitive. Tabs mixed with spaces or inconsistent tab widths will cause parsing failures before any job runs.
- Remedy: Use a linter like
yamllintoractionlintintegrated into your pre-commit hooks.
- Remedy: Use a linter like
- Missing or Incorrect Secrets: A deployment step fails with an unhelpful
401 Unauthorizedor403 Forbidden.- Remedy: Check that the secret name in your YAML matches the secret key in your repository settings exactly. Remember that pull requests from forks usually do not have access to production secrets by default.
- Runner Environment Discrepancies: A build succeeds on a developer’s Mac laptop but fails inside the Linux CI runner.
- Remedy: Containerize your build steps. Run tests inside consistent Docker images (e.g.,
golang:1.22-alpineornode:20-bookworm) both locally and inside your CI pipeline to eliminate OS-level differences.
- Remedy: Containerize your build steps. Run tests inside consistent Docker images (e.g.,
- Flaky Tests or Resource Constraints: Tests pass locally but intermittently fail in CI due to memory limits or race conditions.
- Remedy: Monitor runner CPU and RAM utilization. Run test suites with concurrency limits if workers are competing for memory on small agent instances.
- Stale Caches and Artifact Drift: A build fails because an old dependency version was preserved in a pipeline cache.
- Remedy: Include package lockfile hashes in your cache keys (e.g.,
cache-npm-${{ hashFiles('package-lock.json') }}). When dependencies change, the cache key updates automatically.
- Remedy: Include package lockfile hashes in your cache keys (e.g.,
3. Debugging Tools
- Local Runners: Tools like
actallow you to run GitHub Actions locally inside Docker containers, speeding up feedback loops without spamming your Git commit log. - Interactive SSH Sessions: Many platforms (such as CircleCI and GitHub Actions via custom actions) allow you to SSH directly into a running or failed build container to inspect file systems and run commands manually.
Reusability and Standardization
As organizations scale past a few dozen repositories, maintaining individual pipeline definitions inside every single repository leads to massive duplication. If your organization changes its Docker registry or security scanning tool, updating hundreds of separate YAML files manually is inefficient.
Mechanisms for Reusability
- Reusable Workflows (GitHub Actions): Call centrally managed workflow files stored in a dedicated security or platform repository. Downstream projects pass inputs and secrets without defining the underlying steps.
- Includes and Components (GitLab CI/CD): Use the
include:keyword or the GitLab CI/CD Component Catalog to pull in standardized snippets from centralized repositories. - Shared Libraries (Jenkins): Centralize complex Groovy functions and pipeline definitions in an external Git repository accessible to all Jenkins jobs.
- Templates (Azure Pipelines): Reference external YAML templates that define standardized jobs, steps, or variable groups.
       +---------------------------------------------+
       |   Central Platform/DevSecOps Repository      |
       |  (Houses standard, audited pipeline blocks)  |
       +----------------------+----------------------+
                              |
              Imports & Reuses Workflow / Template
                              |
        +---------------------+---------------------+
        |                                           |
        v                                           v
+-------+---------------+                   +-------+---------------+
| App Service Repo "A"  |                   | App Service Repo "B"  |
| Uses standard lint &  |                   | Uses standard lint &  |
| security scan template|                   | security scan template|
+-----------------------+                   +-----------------------+
The Balance: Central Standards vs. Developer Autonomy
Standardization should make things easier for developers, not act as a roadblock:
- Centralize Non-Negotiables: Enforce organizational compliance, secret scanning, software license checks, and image signing inside shared templates managed by platform or security teams.
- Keep Build Logic Local: Allow application teams to control their own test commands, build arguments, and package scripts. Application teams know best how their code compiles; platform teams know best how releases must be secured.
- Version Your Shared Templates: Never point application pipelines to an unversioned
mainbranch of a shared template repository. Use semantic versioning (e.g.,@v2.1.0) so updates do not inadvertently break builds across the organization.
Core Benefits of Pipeline as Code
When organizations adopt Pipeline as Code, they see practical improvements across their entire delivery cycle:
- Traceability and Auditability: Regulated industries require strict records of how software is verified and deployed. Git commits show who introduced a change, who reviewed it, and which tests validated it.
- Rapid Disaster Recovery: If a CI/CD server is destroyed or corrupted, zero pipeline configuration is lost. Spinning up a new instance and pointing it at your Git repositories restores the entire deployment automation ecosystem.
- Seamless Branch Testing: Feature branches carry their own pipeline definitions. If a developer needs to test a new compiler flag or test framework, they can alter the pipeline on their working branch without impacting other team members.
- No UI-Induced Configuration Drift: Over time, manual systems suffer from undocumented, minor changes made by different administrators. Code files ensure environments remain identical over months and years.
- Standardized Developer Experience: When onboarding new engineers, they do not need unique permissions to inspect a separate build server UI. They open the repository, read the pipeline configuration file, and understand how the application is built and deployed.
Challenges and Limitations
Despite its advantages, Pipeline as Code introduces its own operational complexities that teams must manage:
- Syntax Complexity and Abstraction Fatigue: Modern CI/CD configurations can span hundreds of lines of complex YAML with nested arrays, conditional operators, and custom formatting.
- Mitigation: Keep pipeline definitions concise. Offload complex deployment logic into dedicated, locally testable scripts (Bash, Python, Go) or container images rather than writing 40-line bash snippets inside YAML strings.
- Platform Lock-In: Pipeline files are not portable between tools. A GitHub Actions workflow will not run inside GitLab CI/CD or Jenkins without a complete rewrite.
- Mitigation: Keep your CI/CD configuration as a thin wrapper. If your pipeline mainly calls standard commands like
make test,docker build, orterraform apply, migrating to a new CI engine in the future becomes straightforward.
- Mitigation: Keep your CI/CD configuration as a thin wrapper. If your pipeline mainly calls standard commands like
- Long Feedback Loops: Waiting for remote cloud runners to pick up, execute, and report failures can slow down initial pipeline development.
- Remedy: Use local linters, schema validation plugins in your IDE, and containerized local runners to test basic workflow logic before pushing commits.
- Template Dependency Breakages: Upgrading a centralized, shared pipeline template can break builds across multiple team repositories simultaneously.
- Remedy: Require semantic versioning for shared components, write integration tests for shared templates, and provide deprecation windows for breaking changes.
Real-World Use Cases
Pipeline as Code provides value across varied engineering scenarios:
1. Automated Web Application Testing
- Scenario: A front-end web project requires linting, unit tests, and end-to-end browser verification across multiple browsers on every pull request.
- How PaC Helps: The repository’s workflow file orchestrates parallel matrix jobs to run unit tests in seconds and spins up containerized headless browsers for end-to-end checks, blocking merge buttons automatically if tests fail.
2. Containerized Microservice Delivery to Kubernetes
- Scenario: A team manages dozens of independent Go microservices running on a Kubernetes cluster.
- How PaC Helps: A shared pipeline template builds the Go binary, builds a lightweight container image, signs it with a cryptographic tool, scans it for CVE vulnerabilities, and updates a GitOps deployment repository with the new image tag.
3. Infrastructure as Code (IaC) Validation
- Scenario: Platform engineers use OpenTofu or Terraform to manage cloud infrastructure.
- How PaC Helps: A pipeline triggers on pull requests to run
terraform fmt, validate configurations against organizational policies using Open Policy Agent (OPA), and executeterraform plan, posting the projected infrastructure changes directly into the PR comments for peer review.
4. Multi-Environment Staged Releases
- Scenario: An enterprise application requires automatic deployment to a development environment, followed by automated integration tests, automatic promotion to staging, and an authenticated approval gate before deploying to production.
- How PaC Helps: The pipeline models environments natively. The pipeline automatically pauses after the staging run, issues a notification to release managers, and proceeds with the production deployment only after approval is logged in the system.
Production Best Practices
To keep pipelines maintainable, fast, and secure at scale, follow these production-tested practices:
- Treat Pipelines as Production Software: Subject every line of pipeline code to the same standards as your application: lint it, review it, test it, and refactor it when it becomes messy.
- Keep Pipeline Files Readable: Give every job and step a clear, descriptive name. Avoid cryptic one-liners that leave developers guessing what a step actually does during an outage.
- Optimize for Speed: Slow pipelines hurt engineering velocity. Cache package dependencies, use parallel matrix strategies, and run independent checks (such as linting and unit tests) concurrently.
- Fail Fast: Order your pipeline stages intelligently. Place quick, low-resource checks (like formatting and linting) at the very beginning of the pipeline so developers receive feedback within seconds rather than waiting for long build jobs to finish.
- Separate Secrets from Code: Never commit passwords, tokens, or private keys to your pipeline repository. Use short-lived credentials via OIDC or pull secrets from a managed vault at runtime.
- Make Error Messages Actionable: When a step fails, output clear instructions explaining what went wrong and how to fix it (e.g., “Run
npm run lint:fixlocally to resolve formatting issues”). - Prune Dead Configurations: Remove deprecated jobs, commented-out steps, and obsolete scripts regularly to prevent configuration sprawl.
Frequently Asked Questions
What is Pipeline as Code in DevOps?
Pipeline as Code is the practice of defining, storing, and managing CI/CD delivery workflows in version-controlled text configuration files located alongside application source code.
Why is Pipeline as Code important?
It eliminates human error, undocumented configuration changes, and tribal knowledge associated with manually clicking through a web UI. It makes software builds and deployments reproducible, auditable, and easy to review through standard Git pull request workflows.
What is the difference between Pipeline as Code and CI/CD?
CI/CD refers to the broader software delivery methodology of frequently integrating code changes and automatically delivering them to target environments. Pipeline as Code is the specific implementation technique of defining those CI/CD processes as code files rather than manually configuring them through graphical interfaces.
Which tools support Pipeline as Code?
Nearly all modern CI/CD engines support Pipeline as Code, including GitHub Actions, GitLab CI/CD, Jenkins (via Jenkinsfiles), Azure Pipelines, CircleCI, Tekton, and AWS CodePipeline.
What is a Jenkinsfile?
A Jenkinsfile is a text file that contains the definition of a Jenkins Pipeline. It is written using either Declarative or Scripted Groovy syntax and is stored in the root of an application source control repository.
Is YAML required for Pipeline as Code?
No. While YAML is the most widely adopted format across tools like GitHub Actions, GitLab CI/CD, and Azure Pipelines, other platforms use different languages. For instance, Jenkins uses Groovy DSLs, and Tekton uses Kubernetes CRDs.
How does Pipeline as Code improve security?
It allows security teams to enforce automated quality gates, vulnerability scans, and policy checks early in the development lifecycle. Additionally, storing pipelines in Git provides a clear audit trail of who made changes to build and deployment processes.
Can pipeline definitions be reused across projects?
Yes. Modern platforms provide mechanisms for reusability, such as GitHub Actions Reusable Workflows, GitLab CI/CD Components and Includes, Jenkins Shared Libraries, and Azure Pipelines Templates.
How do you test a pipeline definition?
Teams test pipeline definitions using syntax linters (such as yamllint or actionlint), local execution tools (such as act), and by testing workflow changes on isolated feature branches before merging them into main branches.
What are the common challenges of Pipeline as Code?
Key challenges include managing complex YAML files, dealing with platform lock-in, debugging issues on remote runners, preventing configuration duplication, and securely managing credentials and access permissions.
Final Thoughts
Adopting Pipeline as Code brings the rigor, discipline, and auditability of software engineering directly to your delivery process, replacing undocumented ClickOps with reliable automation. Moving away from manual setup does not require transforming your entire infrastructure overnight; start small by automating a single test workflow on pull requests, establish sound secret management and review habits, and expand incrementally into full continuous deployment as your team’s confidence grows.