



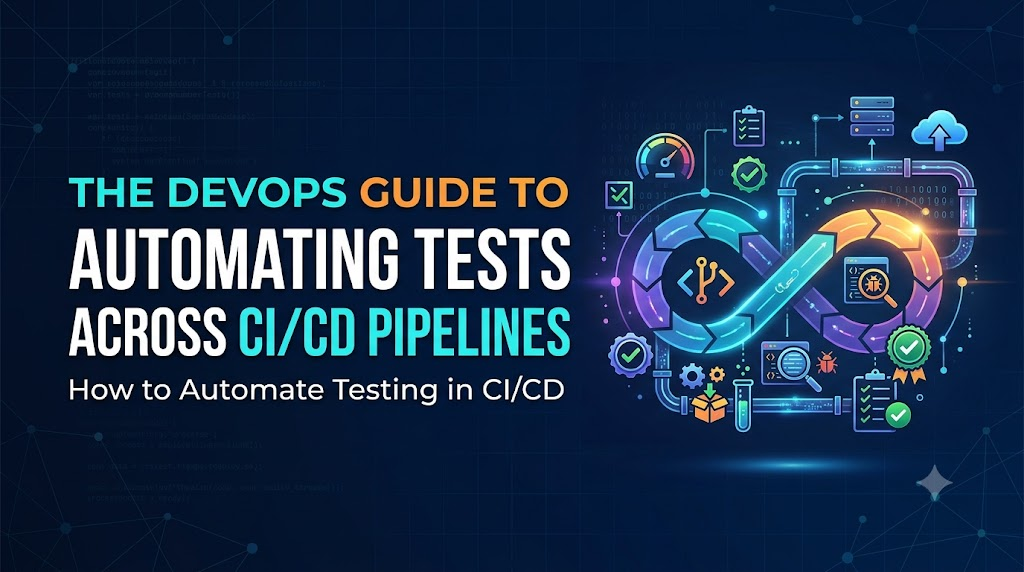
In modern software delivery, manual testing alone creates severe bottlenecks that delay release cycles and increase the risk of regressions slipping into production environments. Integrating automated testing into a continuous integration and continuous delivery (CI/CD) workflow solves this friction by executing repeatable, structured verification checks every time code changes, dependencies are updated, or deployment artifacts are built. While automation accelerates developer feedback and ensures baseline stability across services, it works in tandem with exploratory testing, human architectural review, and operational monitoring rather than replacing them. For engineering teams and practitioners looking to build robust pipelines and master continuous delivery practices, DevOpsSchool provides practical training and comprehensive learning pathways across modern DevOps methodologies.
1. What Is Test Automation in CI/CD?
To understand how automated testing functions within automated software delivery, teams must first distinguish between the three progressive stages of modern software delivery pipelines:
- Continuous Integration (CI): The practice where developers frequently merge code changes into a central repository, usually multiple times per day. Each integration triggers an automated build sequence and early validation tests to detect syntax errors, structural defects, and immediate regressions as early as possible.
- Continuous Delivery (CD): An extension of continuous integration where build artifacts that pass automated validation are automatically packaged, configured, and deployed to staging or pre-production environments. In continuous delivery, the software remains in a verified, releasable state at all times, though the final trigger to deploy to production may involve human approval or business scheduling.
- Continuous Deployment: The operational practice where every code change that successfully passes every automated stage, quality gate, and compliance check across the delivery pipeline is promoted directly and automatically to the production environment without manual intervention.
Test automation in CI/CD is the structured execution of software verification routines via automated scripts, frameworks, and pipeline definitions without requiring human intervention to start, monitor, or record the outcome. These automated tests provide objective, data-driven evidence regarding software behavior, functional correctness, API contract compatibility, system performance, and operational release readiness.
Core Mechanics: From Script to Pipeline
Engineering teams frequently conflate testing terminology. Clarifying these terms helps establish effective delivery architectures:
- Test Automation Script: The concrete, programmatic implementation of a test scenario (for example, a Python script asserting that a database record updates correctly after an HTTP POST request).
- Test Automation Framework: The scaffolding, conventions, libraries, and utilities that support test script execution (such as Pytest, JUnit, or Playwright). The framework provides assertion libraries, execution fixtures, parameterization utilities, and reporting hooks.
- Test Suite: A curated collection of test scripts grouped logically by target component, test type, execution speed, or business priority (for example, a smoke test suite versus an end-to-end regression suite).
- Test Runner: The runtime engine or CLI utility that discovers, executes, parameterizes, and measures test scripts using a specific framework, outputting standardized exit codes and execution summaries (such as
mvn test,pytest -v, ornpm test). - CI/CD Pipeline: The top-level orchestration workflow (defined via declarative configuration files such as YAML) that checks out source code, provisions build environments, runs compilation steps, coordinates test runners across distinct execution stages, evaluates quality gates, publishes artifacts, and manages deployment workflows.
Manual Testing vs. Automated Testing
Automated testing is not a wholesale replacement for manual evaluation; rather, both approaches serve distinct, complementary purposes throughout the software development lifecycle.
| Dimension | Manual Testing | Automated Testing |
| Repeatability | Prone to human fatigue, inconsistent execution steps, and variable interpretation of results. | Highly deterministic; executes identical actions, inputs, assertions, and checks on every run. |
| Execution Speed | Slow; bounded by human reading, clicking, data entry, and manual observation speed. | Fast; executes at machine and network speed; parallelizable across distributed runners. |
| Initial Investment | Low initial cost; requires minimal upfront scripting, tooling, or infrastructure setup. | High upfront engineering effort to establish frameworks, mocks, test fixtures, and pipeline jobs. |
| Ongoing Maintenance | Scales linearly with application scope, requiring more human hours as features expand. | Requires continuous refactoring to adapt to architectural changes, API evolution, and UI updates. |
| Exploratory Capabilities | High; excels at uncovering unexpected edge cases, visual layout defects, and usability issues. | Low; strictly limited to validating explicit assertions and pre-programmed conditions. |
| Ideal Use Cases | Exploratory testing, usability validation, ad-hoc bug reproduction, early-stage prototyping. | Regression testing, unit validation, build verification, API contracts, performance thresholds. |
Not every test scenario warrants automation. Automating a volatile, short-lived user interface feature that changes daily introduces high maintenance overhead with minimal long-term value. Conversely, omitting automation for core financial calculations, authentication flows, or database transactions creates severe operational risk. Automation delivers its highest return on investment when applied to stable, critical, repetitive, and deterministic business logic.
2. Why Automate Testing in CI/CD?
Integrating automated testing directly into software delivery workflows provides several key technical and operational benefits:
- Earlier Defect Detection: By executing automated tests immediately upon code push or pull request creation (a practice known as shift-left testing), developers identify bugs while the implementation context is fresh in their minds, significantly reducing remediation effort.
- Faster Developer Feedback: Instead of waiting days for a separate QA cycle, engineers receive actionable diagnostic outputs within minutes of pushing code, accelerating feature development and pull request reviews.
- Repeatable Test Execution: Automated tests eliminate variations introduced by differing local developer machine setups, manual configuration steps, or subjective human interpretations of test instructions.
- Reduced Repetitive Manual Effort: Routine regression checks, smoke tests, and contract verifications run programmatically, allowing quality assurance specialists to dedicate time to exploratory testing, security audits, and edge-case modeling.
- Consistent Release Validation: Every deployment artifact undergoes an identical, auditable series of verification checks before it is promoted to subsequent environments or cleared for production release.
- Effective Regression Prevention: As codebases grow across multiple teams, automated suites ensure that new features, package upgrades, or refactored modules do not inadvertently disrupt pre-existing application functionality.
- Cross-Functional Alignment: Automated test definitions, written in accessible code or clear behavior-driven specifications, establish a single, shared definition of system requirements between developers, QA engineers, and product owners.
- Informed Release Decisions: Objective pass/fail criteria, code coverage reports, and defect trends provide engineering leadership with empirical indicators of system stability rather than subjective release readiness assessments.
- Support for High-Frequency Deployments: Microservices architectures and continuous deployment models are practically impossible to maintain safely without robust, automated verification safeguarding each service boundary.
- Architectural Visibility: Test suites act as living, executable documentation that demonstrates how components interact, handle errors, and process data across the platform.
Dependencies, Costs, and Operational Risks
The benefits of automated testing depend heavily on the quality, speed, and reliability of the test suites themselves. When test suites are poorly architected, automation can actively hinder delivery velocity:
- Test Maintenance Overhead: If tests are tightly coupled to ephemeral implementation details (such as specific internal private methods or volatile HTML DOM structures), simple code refactorings will trigger extensive test failures, requiring constant developer remediation.
- Pipeline Congestion: Large, unoptimized, sequential test suites that run for hours create developer bottlenecks, encouraging engineers to batch large volumes of code together or bypass pipeline stages to meet delivery deadlines.
- The Risk of Flaky Tests: Suites that intermittently pass and fail due to timing issues or shared state erode trust in the pipeline. Once developers assume failures are “just pipeline noise,” critical production defects are easily overlooked.
- False Confidence via Ineffective Metrics: Striving exclusively for high code coverage metrics without evaluating assertion depth can lead to tests that execute code paths without verifying meaningful business outcomes.
3. Types of Tests to Automate in CI/CD
A mature continuous testing strategy employs different types of tests across various stages of the delivery lifecycle. Each test category addresses specific risks, targets distinct layers of the software architecture, and carries unique trade-offs regarding execution speed, isolation, and infrastructure requirements.
+-------------------------------------------------------------+
|                  End-to-End & UI Testing                    |
|             (Broad Scope, Slower, High Overhead)            |
+-------------------------------------------------------------+
|              Integration & API / Contract Testing           |
|            (Component Interactions, Network Boundaries)     |
+-------------------------------------------------------------+
|                     Unit Testing (Foundation)               |
|            (Isolated Logic, Fast, Highly Deterministic)     |
+-------------------------------------------------------------+
3.1 Unit Testing
Unit tests isolate and validate the smallest testable units of source code—typically functions, methods, or class behaviors. External dependencies such as databases, third-party HTTP services, file systems, and message queues are replaced with in-memory test doubles (mocks, stubs, or fakes).
- Value: Extremely fast execution (milliseconds per test), highly deterministic, and provides precise root-cause localization when failures occur.
- Considerations: Unit tests validate business algorithms and internal logic, but they cannot verify whether two components will interact correctly over an actual network connection or database driver.
3.2 Integration Testing
Integration tests evaluate whether distinct modules, services, or internal subsystems communicate properly. These tests verify data persistence through real database engines, message serialization over message queues, and cache retrieval mechanics.
- Value: Catches schema mismatches, query syntax errors, serialization failures, and transactional boundary issues that unit tests intentionally bypass.
- Considerations: Slower than unit tests and requires realistic supporting dependencies. Modern teams frequently utilize lightweight, containerized dependencies (such as via Docker or ephemeral test containers) to keep environments consistent and isolated.
3.3 API Testing
API tests validate application endpoints over network protocols (such as HTTP, gRPC, or GraphQL) without rendering a user interface. They verify request validation, HTTP status codes, payload structures, schema definitions, authentication policies, authorization headers, error handling, and business rule enforcement.
- Value: Provides robust end-to-end service validation with significantly higher speed, lower maintenance, and greater stability than browser-driven UI testing.
- Considerations: API tests require stable network routes, active service instances, and carefully managed test payloads or accounts with varied permission levels.
3.4 End-to-End (E2E) Testing
End-to-end tests simulate complete real-world user or system journeys through the application from start to finish. For example, an E2E test might simulate an end user registering an account, verifying an email, logging in, adding an item to a shopping cart, executing a checkout, and validating downstream order events.
- Value: Validates overall system integrity across frontend interfaces, backend APIs, data stores, third-party webhooks, and asynchronous background workers simultaneously.
- Considerations: E2E tests are complex to author, slow to execute, and highly susceptible to environmental flakiness, data collisions, and external network timeouts. They should be reserved for high-value, critical business paths.
3.5 Regression Testing
Regression testing is not necessarily a distinct category of test code, but a strategic selection of previously authored unit, integration, API, and E2E tests executed against new code changes to verify that pre-existing functionality remains intact.
- Value: Prevents known bugs from reappearing and ensures backward compatibility as systems evolve.
- Considerations: As the application grows, running the full regression suite on every minor pull request becomes impractical. Teams often split regression tests into fast “smoke” subsets for PR checks and comprehensive suites for nightly or pre-release pipeline runs.
3.6 UI Testing
UI tests focus on the presentation layer, verifying that visual components render correctly, user input controls respond appropriately, and client-side logic behaves as expected across different web browsers, viewport sizes, and operating systems.
- Value: Verifies the actual visual and functional layer that human users interact with, catching client-side JavaScript execution errors and DOM manipulation bugs.
- Considerations: UI automation scripts often break when classes, IDs, or layout hierarchies change. Teams should use resilient selector strategies (such as testing IDs, ARIA roles, or user-facing accessibility labels) rather than brittle, deep XPath or CSS selectors.
3.7 Performance Testing
Automated performance testing evaluates how a system behaves under expected, peak, or sustained operational workloads.
- Load Testing: Verifies that the system meets response-time and throughput service level objectives (SLOs) under typical expected traffic volumes.
- Stress Testing: Pushes the application beyond normal operational limits to identify failure points, evaluate graceful degradation, and verify recovery mechanics.
- Endurance (Soak) Testing: Runs a steady load over an extended period to identify memory leaks, resource exhaustion, or unclosed database connection pools.
- Pipeline Placement: While full-scale stress and endurance tests belong in dedicated, isolated staging environments or scheduled nightly runs, lightweight performance regression checks (such as validating p95 response times on critical API endpoints) can be integrated into pre-release CI/CD stages.
3.8 Security Testing
Automated security testing embeds defensive checks throughout the delivery pipeline (a core DevSecOps practice) to identify vulnerabilities before code reaches production:
- Static Application Security Testing (SAST): Scans source code repositories for common security weaknesses, insecure coding patterns, and compliance violations without executing the code.
- Dynamic Application Security Testing (DAST): Analyzes running application endpoints from the outside, injecting simulated attack vectors (such as cross-site scripting or SQL injection payloads) to identify runtime vulnerabilities.
- Software Composition Analysis (SCA): Scans open-source and third-party dependencies against vulnerability databases (such as CVE lists) to detect unpatched packages or restrictive licenses.
- Secrets Detection: Continuously scans code commits and pipeline configurations for accidentally committed API tokens, private keys, database passwords, and credentials.
- Infrastructure as Code (IaC) Scanning: Analyzes Terraform, CloudFormation, Helm charts, or Kubernetes manifests for insecure configurations, such as unencrypted storage buckets or overly permissive security groups.
3.9 Smoke and Sanity Testing
- Smoke Testing: A small, fast suite of critical health checks executed immediately following a build or deployment to verify that the core application infrastructure is operational (e.g., processes start, database connections establish, and the main landing endpoint returns HTTP 200). If the smoke tests fail, the build is rejected immediately, halting subsequent expensive tests.
- Sanity Testing: A focused verification executed after receiving a minor patch or bug fix to quickly confirm that the targeted defect is resolved and related functional areas are fundamentally operational.
3.10 Acceptance Testing
Automated acceptance tests verify that the system satisfies specific, agreed-upon business requirements and user stories. Often structured around Behavior-Driven Development (BDD) patterns using natural language syntax (e.g., Given-When-Then), these tests align functional implementation directly with stakeholder expectations.
Comparison of Test Automation Types
| Test Type | Primary Purpose | Ideal Pipeline Stage | Relative Execution Cost | Practical Example |
| Unit | Validate isolated functions and business logic | Pre-commit, Pull Request, Commit Build | Very Low (Seconds) | Asserting that a currency conversion function rounds tax amounts accurately. |
| Integration | Validate communication between components and data stores | Post-compilation, PR verification | Low to Medium (1–5 minutes) | Confirming an order repository can write and retrieve JSON records from PostgreSQL. |
| API / Contract | Validate API payloads, status codes, schemas, and service contracts | PR verification, Post-build verification | Low to Medium (1–5 minutes) | Verifying that /api/v1/users returns HTTP 401 when an authorization token is expired. |
| Security (SAST/SCA) | Detect insecure coding patterns and vulnerable dependencies | Pull Request, Commit Build | Low (1–3 minutes) | Scanning package-lock.json for known vulnerabilities via an SCA scanner. |
| Smoke | Confirm environment deployment and basic service health | Immediately post-deployment (Staging/Prod) | Very Low (< 1 minute) | Querying /healthz to confirm web servers, cache, and database connections are live. |
| UI Automation | Verify visual workflows and client-side interactions | Post-deployment to ephemeral or staging env | Medium to High (5–15 minutes) | Automating a browser to type credentials into a login form and verify the dashboard renders. |
| End-to-End | Validate full system workflows across all services | Dedicated test environment, Pre-release stage | High (15–45 minutes) | Completing an entire customer registration, credit card payment, and order confirmation path. |
| Performance | Measure response times, throughput, and resource limits | Pre-release staging, Scheduled nightly runs | High (30+ minutes) | Simulating 2,000 concurrent user checkouts on an isolated cluster to verify p99 latency stays below 500ms. |
4. Designing a CI/CD Pipeline for Automated Testing
A dependable CI/CD pipeline requires a structured execution flow. The overarching architectural principle is simple: fail fast, fail cheaply, and deliver immediate feedback.
Tests that are fast, deterministic, and inexpensive to run should execute early in the pipeline. Slower, broader, and more resource-intensive tests should only execute after the software has proven its fundamental correctness through earlier quality gates.
Progressive Testing Pipeline Flow
+--------------------------------------------------------------------------+
| 1. Code Commit / Pull Request Trigger                                    |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 2. Static Checks: Linting, Format Validation, Secrets Detection          |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 3. Dependency Resolution & SAST / SCA Security Scanning                  |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 4. Build Compilation & Fast Unit Test Execution                          |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 5. Component & Integration Tests (Isolated Ephemeral Containers)         |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 6. Container Packaging, Image Scanning & Artifact Publishing             |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 7. Deployment to Ephemeral Review or Staging Environment                 |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 8. Deployment Smoke Tests & Health Check Validations                     |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 9. Parallel API Contract Verification & Critical E2E Workflows           |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 10. Quality Gate Evaluation (Coverage, Security, Performance)            |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 11. Production Promotion (Manual Approval or Continuous Deployment)      |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 12. Post-Release Verification & Canary Health Monitoring                 |
+--------------------------------------------------------------------------+
Stage-by-Stage Implementation Blueprint
| Pipeline Stage | Purpose | Primary Test & Verification Types | Pass/Fail Handling Policy |
| 1. Source Validation | Ensure code meets formatting, style, and security syntax baselines. | Static linters, code formatters, static secrets scanning. | Hard Block: Pipeline halts immediately on lint or secret violation. |
| 2. Build & Unit Validation | Validate isolated logic and ensure compile-time integrity. | Compilation, unit tests, in-memory logic assertions. | Hard Block: Any unit test failure cancels subsequent jobs. |
| 3. Security & Dependency Check | Detect known vulnerabilities in third-party libraries. | SAST, Software Composition Analysis (SCA). | Hard Block on Critical/High CVEs; Warning on Low/Medium CVEs. |
| 4. Integration & Service Layer | Verify component interaction using test containers. | Database integration, broker persistence, API contract tests. | Hard Block: Failures indicate data or contract incompatibilities. |
| 5. Packaging & Image Audit | Ensure built container images are secure and immutable. | Container vulnerability scanning, image signing verification. | Hard Block if the container contains known root exploits or critical CVEs. |
| 6. Staging Deployment & Smoke | Confirm the deployment succeeded and core services run. | Infrastructure health checks, readiness probes, smoke tests. | Hard Block & Auto-Rollback: If smoke tests fail, deployment rolls back. |
| 7. E2E & Browser Validation | Validate critical business transactions end-to-end. | Targeted browser automation, cross-service E2E flows. | Hard Block for critical flows; failed tests quarantined for triage. |
| 8. Release Quality Gate | Evaluate aggregate stability metrics across all stages. | Aggregate pass rates, code coverage thresholds, policy checks. | Hard Block: Release artifact is withheld if thresholds are breached. |
| 9. Post-Release Monitoring | Verify live production health and monitor user telemetry. | Production synthetic monitoring, canary error budget tracking. | Automated Rollback if production error rates spike above baseline. |
Pipeline Failure Policies
A clear failure policy prevents confusion:
- Critical Failures (Hard Block): Unit test failures, compilation breaks, critical security vulnerabilities, database migration errors, and deployment smoke test failures must halt the pipeline immediately. No downstream jobs should run, and no deployment artifact should be produced.
- Non-Blocking Findings (Warnings): Low-severity style inconsistencies, non-critical static analysis recommendations, or minor dependency updates can be surfaced as pipeline warnings or automated review comments without blocking immediate deployment, provided they are tracked in the engineering backlog.
5. The Test Automation Pyramid and Test Selection
The Test Automation Pyramid—originally popularized by Mike Cohn and refined across the software industry—serves as a core visual and conceptual heuristic for designing a balanced testing portfolio.
       / \
      /   \     End-to-End & UI Tests  (Smallest Quantity, Slower, Higher Cost)
     /     \
    /-------\
   /         \   Integration & API Tests (Moderate Quantity, Fast, Network/Data)
  /           \
 /-------------\
/               \ Unit Tests             (Largest Quantity, Milliseconds, Isolated)
-----------------
Deconstructing the Pyramid Layers
- The Broad Base (Unit Tests): Unit tests should form the largest volume of tests in your repository. Because they execute in memory in fractions of a second and do not require external network connections or database infrastructure, they provide immediate, highly specific diagnostic feedback.
- The Middle Tier (Integration and Service/API Tests): This layer validates interactions between application modules, services, databases, and third-party APIs. They are fewer in number than unit tests because they require running dependencies and network operations, but they offer critical validation of boundary contracts and serialization mechanics.
- The Top Tier (End-to-End and UI Tests): The apex of the pyramid comprises end-to-end user journeys executed across real browsers or fully deployed application clusters. Because these tests involve the entire stack, they take significantly longer to run and are more susceptible to environment and data inconsistencies. Consequently, they should be reserved for critical business workflows.
Adapting the Model: Context Over Dogma
While the test pyramid provides an excellent starting framework, it is a design heuristic rather than an unyielding law. Different architectural paradigms require teams to adjust their test distribution:
- Microservices and Event-Driven Architectures: In microservices environments, extensive unit testing of simple CRUD or routing controllers often provides less value than robust API contract testing (e.g., using consumer-driven contract tools) and component integration tests that verify message serialization across Kafka or RabbitMQ topics. This structure often resembles an “inverted pyramid” or an “hourglass” shape, where service-layer and contract tests outnumber pure unit tests.
- Legacy Systems and Monoliths: Teams inheriting monolithic legacy systems lacking modular interfaces often find it difficult to write pure unit tests without massive, high-risk refactoring. In these scenarios, teams frequently start by building an outer perimeter of API and integration tests to ensure safety before progressively refactoring code to support unit testing.
Anti-Patterns to Avoid
- The “Ice Cream Cone” (Inverted Pyramid): An anti-pattern where an organization maintains few unit tests, some integration tests, and a massive, brittle suite of automated UI and manual end-to-end tests. This leads to slow pipelines, high maintenance costs, frequent false positives, and delayed release cycles.
- Testing Implementation Details: Unit tests that assert internal private variable states or mirror exact lines of code rather than verifying observable inputs and outputs create brittle suites that break whenever code is refactored, even when the software functions perfectly.
- Over-Mocking in Integration Tests: When integration tests mock every database, queue, and external dependency, they cease to be integration tests. They become slow unit tests that fail to detect real-world integration bugs, such as incompatible SQL dialect queries or broken connection pools.
Risk-Based Test Selection
Rather than executing every test in the repository on every single commit, mature engineering organizations employ risk-based test selection:
- Impact Analysis: Running only the tests that cover the code paths modified in a specific pull request (e.g., executing frontend unit tests only when files in
/src/ui/change). - Tiered Suites: Executing fast unit, static, and critical smoke tests on pull requests, while scheduling broader, long-running end-to-end, performance, and cross-browser suites to run periodically (e.g., nightly or pre-release).
6. Choosing Test Automation Tools
Selecting the right tooling is critical for pipeline reliability. The ideal tool depends on your application’s architecture, language ecosystem, team skill set, and operational requirements.
Tool Selection Evaluation Criteria
When evaluating test frameworks and automation platforms for CI/CD integration, assess:
- Language and Framework Parity: Tools that align with the application’s primary programming language allow developers to write tests without switching context or learning disparate toolchains.
- Execution Speed and Parallelism: Does the tool support native parallel test thread execution across multi-core CI runners or distributed worker nodes?
- Diagnostic Capabilities: Does the framework produce structured, machine-readable output formats (such as JUnit XML or TAP) alongside clear console logs, screenshots, and network traces on failure?
- Headless and Container Support: Can the tool run reliably in headless, non-interactive container environments without requiring a local display server?
- Ecosystem and Maintenance: Is the tool actively maintained, backed by an active open-source community or reliable vendor, and supported by extensive documentation?
Tool Category Matrix
+---------------------------------------------------------------------------------------+
|                              CI/CD Pipeline Orchestration                             |
|              (GitHub Actions, GitLab CI/CD, Jenkins, Azure DevOps Pipelines)          |
+---------------------------------------------------------------------------------------+
        |                                   |                                   |
        v                                   v                                   v
+-----------------------+   +-------------------------------+   +-----------------------+
|  Unit & Integration   |   |        API & Contract         |   |    Browser & E2E      |
|  - JUnit / TestNG     |   |  - REST Assured (Java)        |   |  - Playwright         |
|  - pytest (Python)    |   |  - pytest-requests (Python)   |   |  - Cypress            |
|  - Jest / Vitest (JS) |   |  - Postman / Newman           |   |  - Selenium           |
+-----------------------+   +-------------------------------+   +-----------------------+
        |                                   |                                   |
        +-----------------------------------+-----------------------------------+
                                            |
                                            v
                    +-----------------------------------------------+
                    |         Security, Load & Code Quality         |
                    |  - k6 / Apache JMeter (Performance)           |
                    |  - SonarQube / Trivy / Snyk (Sec & Quality)   |
                    +-----------------------------------------------+
The table below outlines common, industry-standard tools across key automated testing domains:
| Category | Representative Tools | Primary Target & Use Case | Key Pipeline Strengths | Operational Considerations |
| Java Unit / Integration | JUnit 5, TestNG | Java and JVM backend unit and integration testing. | Deep integration with Maven/Gradle; native parallel test execution. | Requires structured configuration for containerized integration testing. |
| Python Unit / Integration | pytest | Python services, data pipelines, and machine learning models. | Highly expressive fixture model; extensive plugin ecosystem. | Requires strict virtual environment caching to maintain fast pipeline startup times. |
| JavaScript / TypeScript | Jest, Vitest | Node.js backend services, React/Vue/Angular frontends. | Snapshot testing, fast in-memory execution; native TypeScript support. | Memory consumption can scale rapidly in large test suites without worker limits. |
| API & Contract Testing | REST Assured, Newman (Postman), Pact | RESTful, GraphQL, and microservice contract testing. | Clean domain-specific languages for HTTP assertions; contract validation. | Environment-specific authentication and test data must be carefully parameterized. |
| Browser & UI Automation | Playwright, Cypress, Selenium | Web application user workflows and cross-browser testing. | Automatic waiting mechanisms, network interception, video/trace recordings. | Requires significant runner CPU/memory resources; must handle asynchronous UI timing. |
| Performance Testing | k6, Apache JMeter | Load, stress, and API throughput evaluation. | k6 allows writing tests in JavaScript with low resource utilization. | Full load tests must be run in dedicated environments to avoid skewing results. |
| Security Scanning | Trivy, Snyk, SonarQube, OWASP ZAP | Container vulnerability, SAST, dependency, and dynamic scanning. | Generates SARIF and JSON reports; enforces security baseline quality gates. | Rule sets must be tuned to minimize false positives that interrupt delivery. |
7. Step-by-Step Guide to Automating Testing in CI/CD
Transitioning from manual or fragmented testing to an automated CI/CD pipeline requires an incremental, structured implementation plan. The following twelve steps provide an end-to-end roadmap for building a dependable automated testing workflow.
Step 1: Identify Critical Application Behavior
- Objective: Map out high-risk business paths, core revenue-generating workflows, and critical data transactions that require immediate automated validation.
- Implementation: Collaborate with product owners, business analysts, and quality assurance specialists to identify the core paths through the system (e.g., authentication, checkout processing, data processing). Document the expected inputs, successful outcomes, and known error paths.
- Common Mistakes: Attempting to automate every minor UI interaction or edge case before covering the core business workflows.
- Expected Outcome: A prioritized matrix of functional workflows ranked by business criticality and risk.
Step 2: Review Existing Tests
- Objective: Audit current test coverage, identify redundant or low-value checks, and clean up unstable tests.
- Implementation: Categorize existing tests into unit, integration, and UI layers. Evaluate execution times, pass/fail histories, and assertion depth. Delete obsolete tests that validate deprecated features or merely assert framework plumbing.
- Common Mistakes: Preserving slow, obsolete tests that provide no real confidence, cluttering the pipeline with noise.
- Expected Outcome: A clean, documented baseline of verified test suites with clear functional ownership.
Step 3: Select a Test Framework
- Objective: Standardize on testing frameworks that align with the engineering stack, support CI execution, and provide clear diagnostic reporting.
- Implementation: Choose established frameworks that integrate with your team’s programming languages (e.g.,
pytestfor Python,JUnit 5for Java,Vitest/Playwrightfor TypeScript). Ensure the framework supports parameterization, setup/teardown fixtures, and standardized report generation (such as JUnit XML). - Common Mistakes: Selecting heavy, proprietary tools that cannot easily run in headless container environments or require graphical user interfaces.
- Expected Outcome: Standardized, well-documented test frameworks integrated into the project’s dependency configurations.
Step 4: Prepare the Test Environment
- Objective: Ensure test execution environments are isolated, reproducible, and configurable via code.
- Implementation: Use containerization (such as Docker) or infrastructure-as-code definitions to provision consistent runtime environments. Ensure all external connection endpoints, database credentials, and service URLs are driven by environment variables rather than hardcoded configuration files.
- Common Mistakes: Running tests against shared, mutable development environments where outside activities alter data states midway through execution.
- Expected Outcome: Fully reproducible, automated environment definitions that can be spun up on demand in CI runners.
Step 5: Automate Fast Tests First
- Objective: Implement an initial, rock-solid foundation of fast, deterministic unit and static tests that run in seconds.
- Implementation: Configure linting, formatting checks, secrets scanning, and unit tests to execute on every local commit and pull request. Enforce strict isolation: no network calls, real databases, or filesystem operations within this layer.
- Common Mistakes: Allowing network or database calls to slip into unit tests, causing execution times to escalate.
- Expected Outcome: A pull-request validation job that runs in under two minutes, catching syntax errors and fundamental logic defects immediately.
Step 6: Add Integration and API Tests
- Objective: Verify data persistence, service boundaries, and external interface contracts.
- Implementation: Implement API and service-level integration tests using tools like REST Assured, pytest, or Supertest. Use lightweight, containerized dependencies (such as ephemeral database containers) to run realistic queries, schema migrations, and cache operations.
- Common Mistakes: Relying on shared external third-party services that may rate-limit CI runners or introduce unpredictable network latency.
- Expected Outcome: Automated pipeline jobs that validate API contracts, request payloads, and database transactions without human intervention.
Step 7: Add Browser and End-to-End Tests
- Objective: Validate complete, high-priority user journeys through the compiled application interface.
- Implementation: Author a focused suite of browser automation tests using modern frameworks (like Playwright or Cypress) to validate critical paths (e.g., sign-up, checkout, critical data submission). Use resilient, accessibility-focused element locators.
- Common Mistakes: Duplicating every unit and integration test scenario at the browser level, resulting in slow, fragile pipelines.
- Expected Outcome: A focused suite of end-to-end browser tests that execute against staging or review deployments.
Step 8: Configure CI/CD Triggers
- Objective: Map test suites to appropriate stages in the delivery lifecycle based on speed and scope.
- Implementation: Configure pipeline rules:
- Pull Requests: Linters, unit tests, security scans, and fast integration tests.
- Post-Merge to Main: Full integration suites, container builds, and deployment to staging.
- Post-Staging Deployment: Smoke tests, followed by critical E2E and API regression suites.
- Scheduled (Nightly): Long-running performance, endurance, and exhaustive cross-browser regression suites.
- Common Mistakes: Triggering the entire regression and performance test portfolio on every minor documentation update or branch commit.
- Expected Outcome: An efficient, multi-tiered trigger strategy that delivers rapid feedback during development while preserving comprehensive pre-release validation.
Step 9: Publish Test Results
- Objective: Make execution outcomes, diagnostic logs, and failure artifacts immediately visible and actionable to developers.
- Implementation: Configure CI jobs to parse test runner outputs (e.g., JUnit XML, JSON) and display pass/fail summaries directly in the pull request interface. Archive failure artifacts—such as console logs, execution stack traces, browser screenshots, and network activity traces—for rapid debugging.
- Common Mistakes: Requiring developers to dig through thousands of lines of raw, unformatted CI console logs to determine which test assertion failed.
- Expected Outcome: Clear, contextual reporting integrated directly into code review and pipeline dashboards.
Step 10: Define Quality Gates
- Objective: Enforce objective, automated criteria that must be satisfied before artifacts can be merged or promoted.
- Implementation: Establish explicit quality policies: 100% pass rate on unit and integration tests, no new high-severity security vulnerabilities, and adherence to established code coverage baselines on modified code. Configure branch protection rules to block merges when quality gates fail.
- Common Mistakes: Setting quality gates so unrealistically strict that developers routinely request administrative bypasses, eroding the integrity of the process.
- Expected Outcome: Objective, programmatic guardrails that prevent defective or insecure code from reaching production.
Step 11: Optimize Execution
- Objective: Maintain fast feedback loops as test suites expand.
- Implementation: Implement test parallelization across multiple worker threads or distributed runner nodes. Cache package manager dependencies (e.g.,
npm,pip,maven) across runs. Implement test impact analysis to execute only the tests relevant to modified code paths. - Common Mistakes: Over-allocating parallel runners without addressing underlying database or state contention issues, leading to deadlocks and false failures.
- Expected Outcome: A scalable testing pipeline that maintains target execution times even as the application and test suites grow.
Step 12: Monitor and Improve
- Objective: Continuously track pipeline health, eliminate flakiness, and adapt testing strategies based on production outcomes.
- Implementation: Track key operational metrics: pipeline duration, test failure rates, flaky test frequencies, and escaped production defects. Conduct root-cause analyses on any production issue to determine what automated test layer should have caught it.
- Common Mistakes: Treating the CI/CD testing pipeline as a static implementation rather than an evolving, continuously maintained platform.
- Expected Outcome: A self-correcting quality engineering process that continuously improves software reliability and team delivery velocity.
8. Automating Tests in Popular CI/CD Platforms
Modern CI/CD platforms orchestrate the execution of automated test suites across containerized runners, virtual machines, or bare-metal agents. While the underlying test frameworks (such as pytest, JUnit, or Playwright) execute the actual code checks, the CI/CD platform is responsible for managing triggers, provisioning build environments, caching dependencies, coordinating parallel jobs, and capturing test reports.
8.1 GitHub Actions
GitHub Actions uses declarative YAML files placed in .github/workflows/ to automate delivery pipelines.
- Workflow Architecture: Pipelines are structured into workflows, which contain one or more jobs that run on specified runners (e.g.,
ubuntu-latest). Jobs execute sequential steps, which can run shell commands or reusable actions from the GitHub Marketplace. - Test Integration: Tests are typically executed within runner virtual environments or inside specialized Docker containers. Caching actions (like
actions/cacheor language-specific setup actions with built-in caching) cache dependency directories between runs. - Parallel Execution: The
strategy.matrixconfiguration allows teams to execute test suites in parallel across multiple operating systems, language runtime versions, or partitioned test groups. - Reporting: Tools such as the
dorny/test-reporteraction or native workflow commands process JUnit XML test results and annotate failing lines directly on pull request diffs.
YAML
# Illustrative GitHub Actions configuration for automated testing
name: Test Automation Pipeline

on:
  push:
    branches: [ main ]
  pull_request:
    branches: [ main ]

jobs:
  unit-and-integration-tests:
    runs-on: ubuntu-latest
    services:
      postgres:
        image: postgres:15-alpine
        env:
          POSTGRES_DB: testdb
          POSTGRES_USER: testuser
          POSTGRES_PASSWORD: testpassword
        ports:
          - 5432:5432
        options: --health-cmd pg_isready --health-interval 10s --health-timeout 5s --health-retries 5

    steps:
      - name: Check out repository
        uses: actions/checkout@v4

      - name: Set up Python runtime
        uses: actions/setup-python@v5
        with:
          python-version: '3.11'
          cache: 'pip'

      - name: Install dependencies
        run: |
          python -m pip install --upgrade pip
          pip install -r requirements-test.txt

      - name: Execute Static Linting & Secrets Detection
        run: |
          flake8 src/ tests/
          bandit -r src/

      - name: Run Test Suite
        env:
          DATABASE_URL: postgresql://testuser:testpassword@localhost:5432/testdb
        run: |
          pytest --junitxml=reports/junit-report.xml --cov=src tests/

      - name: Publish Test Report Annotations
        uses: actions/upload-artifact@v4
        if: always()
        with:
          name: test-results
          path: reports/junit-report.xml
8.2 GitLab CI/CD
GitLab CI/CD is configured via a single .gitlab-ci.yml file located in the repository root.
- Pipeline Architecture: Pipelines are organized into ordered
stages(e.g.,build,test,package,deploy). Jobs within the same stage run concurrently across available GitLab Runners, while jobs in subsequent stages wait for previous stages to pass successfully. - Test Reports: GitLab natively parses JUnit XML reports via the
artifacts:reports:junitdirective. Test metrics, passed/failed counts, and execution durations are integrated directly into Merge Request interfaces without third-party plugins. - Parallel Execution: The
parallelkeyword allows a job to be replicated across multiple runner instances, allowing test runners to shard large test suites across parallel workers.
YAML
# Illustrative GitLab CI/CD configuration for automated testing
stages:
  - lint
  - test
  - deploy_staging
  - e2e_verification

variables:
  POSTGRES_DB: gitlab_test
  POSTGRES_USER: runner
  POSTGRES_PASSWORD: securepassword

lint_code:
  stage: lint
  image: python:3.11-slim
  script:
    - pip install flake8
    - flake8 src/ tests/

run_unit_and_integration:
  stage: test
  image: python:3.11
  services:
    - postgres:15-alpine
  variables:
    DATABASE_URL: "postgresql://runner:securepassword@postgres:5432/gitlab_test"
  before_script:
    - pip install -r requirements-test.txt
  script:
    - pytest --junitxml=report.xml --cov=src tests/
  artifacts:
    when: always
    reports:
      junit: report.xml
      coverage_report:
        coverage_format: cobertura
        path: coverage.xml
8.3 Jenkins
Jenkins provides an extensible, open-source automation platform centered around declarative or scripted Jenkinsfile definitions.
- Pipeline Architecture: Declarative pipelines divide execution into
pipeline,agent, andstagesblocks. Jenkins relies on a master-agent architecture where agents (often provisioned dynamically as Kubernetes pods or ephemeral cloud VMs) execute build and test jobs. - Test Integration: Build tools such as Maven, Gradle, or npm run within agent containers or pre-installed virtual environments. The
junitpost-action step parses XML test reports, maintaining historical trend graphs across builds. - Failure Handling: The
postblock provides declarative error handling (success,failure,unstable,always), ensuring that diagnostic artifacts and reports are captured even when test suites fail.
Groovy
// Illustrative Declarative Jenkinsfile for automated testing
pipeline {
    agent {
        docker {
            image 'maven:3.9-eclipse-temurin-17'
            args '-v /tmp:/tmp'
        }
    }
    stages {
        stage('Compile & Static Analysis') {
            steps {
                sh 'mvn clean compile spotbugs:check'
            }
        }
        stage('Unit & Integration Tests') {
            steps {
                sh 'mvn test'
            }
        }
        stage('API Contract Verification') {
            steps {
                sh 'mvn verify -DskipUnitTests'
            }
        }
    }
    post {
        always {
            junit '**/target/surefire-reports/*.xml'
            archiveArtifacts artifacts: '**/target/*.jar', fingerprint: true
        }
        failure {
            echo 'Build or test stage failed. Check test reports for details.'
        }
    }
}
8.4 Azure Pipelines
Azure Pipelines (part of the Azure DevOps suite) uses YAML files (such as azure-pipelines.yml) to define cross-platform automation workflows.
- Pipeline Architecture: Pipelines are structured into stages, jobs, and tasks. Jobs can execute on Microsoft-hosted cloud agents or self-hosted agents within private enterprise networks.
- Test Result Publishing: Azure Pipelines provides dedicated, first-party tasks like
PublishTestResults@2andPublishCodeCoverageResults@1, converting standard test outputs into comprehensive dashboard analytics that track pass rates, failures, and execution times over time. - Parallel Execution: The
strategy: paralleldirective enables slicing across test suites to minimize end-to-end execution times.
CI/CD Platform Comparison for Test Automation
| Feature / Dimension | GitHub Actions | GitLab CI/CD | Jenkins | Azure Pipelines |
| Pipeline Configuration | YAML (.github/workflows/) | YAML (.gitlab-ci.yml) | Groovy (Declarative or Scripted Jenkinsfile) | YAML (azure-pipelines.yml) |
| Test Result Integration | Via Marketplace actions or annotations | Native JUnit XML parsing in Merge Requests | Plugin-based (junit step); historical trends | Native tasks (PublishTestResults@2) |
| Containerized Services | services keyword for background containers | services keyword for sidecar containers | Managed via Docker plugins or Kubernetes agents | services keyword or container jobs |
| Parallel Execution | Matrix strategies (strategy.matrix) | parallel keyword / sharding rules | Parallel stages (parallel block); multi-node agents | Matrix and parallel execution strategies |
| Runner Infrastructure | Hosted runners or self-hosted runner binaries | Hosted runners or self-hosted GitLab Runners | Master-Agent model (VMs, Docker, Kubernetes) | Microsoft-hosted or self-hosted agents |
| Best-Fit Ecosystems | GitHub-centric repositories; modern cloud-native apps | Unified DevSecOps platform on GitLab | Highly customized on-prem or enterprise legacy stacks | Microsoft / Azure environments and enterprise teams |
9. Test Data and Test Environment Management
Automated tests are only as reliable as the environments they run in and the data they consume. Inconsistent test data, shared mutable state, and environment drift are the leading causes of non-deterministic, flaky test pipelines.
Reproducible Test Environments
Running automated tests against long-lived, shared, mutable environments introduces severe reliability risks. When multiple pipeline instances execute simultaneously against a shared staging database, their state modifications inevitably collide.
Modern test engineering prioritizes ephemeral environments:
- Containerized Dependencies: Lightweight databases (e.g., PostgreSQL, Redis) and message brokers are provisioned on demand as ephemeral containers directly within the CI runner, run for the duration of the test job, and torn down immediately upon completion.
- Ephemeral Review Environments: For pull requests requiring end-to-end and API testing, platform teams often use Kubernetes operators or tools like Helm to deploy isolated, lightweight copies of the application that live only until the pull request is merged or closed.
Test Data Strategies
Managing data state across thousands of automated test runs requires disciplined data strategies:
- Dynamic Fixtures: Tests generate the precise data records they require at runtime using factory patterns or API endpoints, rather than assuming certain records already exist in the database.
- Database Migrations and Seeding: CI pipelines should apply production database schema migrations against a clean, ephemeral database instance, followed by a deterministic seed script that injects reference data (e.g., supported currencies, country codes) before running tests.
- Transactional Teardowns: In integration test suites, wrapping test operations inside database transactions that roll back at the conclusion of each test ensures that tests leave behind zero lingering state for subsequent runs.
- Synthetic vs. Production Data: Production databases must never be copied directly into test environments without strict masking, sanitization, and compliance controls. Doing so risks exposing personally identifiable information (PII), violating privacy regulations (such as GDPR or HIPAA), and exposing production secrets. Instead, teams should rely on synthetically generated datasets that accurately mirror production schemas, distributions, and boundary constraints without containing real user data.
Mocks, Stubs, and Service Virtualization
Testing against live third-party services (e.g., payment gateways, SMS delivery providers, external credit scoring systems) introduces significant pipeline fragility due to network timeouts, API rate limits, and third-party maintenance windows.
- Test Doubles: Teams should use test doubles (mocks, stubs, fakes) or service virtualization tools (such as WireMock) to simulate third-party responses deterministically.
- Contract Testing: To ensure that mocks do not drift away from real third-party API behaviors over time, teams can implement contract testing (e.g., using Pact). In contract testing, the consumer service and the provider service agree upon a machine-readable specification of inputs and outputs. When the provider updates its API, the contract test suite fails automatically if the change breaks existing consumer expectations.
10. Managing Flaky Tests and Unreliable Pipelines
A flaky test is an automated test that produces inconsistent results—alternating between passing and failing—when executed against the exact same commit under effectively identical conditions. Flaky tests are toxic to CI/CD pipelines: they waste developer time, slow down release cycles, and train teams to ignore pipeline failures, creating an opening for real defects to slip into production.
Root Causes of Test Flakiness
- Asynchronous and Timing Assumptions: Tests that rely on arbitrary sleep statements (e.g.,
sleep(5)) to wait for asynchronous backend operations, UI transitions, or database writes fail whenever CI runners experience transient CPU or I/O contention. - Shared Mutable State: Tests that depend on the execution order of other tests, or that read and write shared database records, global variables, or filesystem paths without proper cleanup between runs.
- Uncontrolled External Dependencies: Tests that make live network calls to third-party endpoints or rely on external DNS resolution, unpinned package mirrors, or live remote servers.
- Resource Contention: Heavy parallel test execution that overwhelms runner CPU, memory, or database connection pools, triggering random timeouts and connection drops.
- Brittle UI Locators: Web tests that select elements using deep, dynamic XPath structures or volatile generated class names that shift with unrelated UI adjustments.
Systematic Remediation Process
+--------------------------------------------------------------------------+
| 1. Detect & Flag                                                         |
|    Identify tests with inconsistent results across identical commits.    |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 2. Quarantine                                                            |
|    Move the test to a non-blocking suite with an owner and deadline.     |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 3. Diagnose & Reproduce                                                  |
|    Review logs, screenshots, and traces; run repeatedly under load.      |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 4. Refactor Root Cause                                                   |
|    Replace sleeps with polling, isolate data state, or mock externals.   |
+--------------------------------------------------------------------------+
                                    |
                                    v
+--------------------------------------------------------------------------+
| 5. Validate & Reinstate                                                  |
|    Confirm stability across multiple consecutive runs; restore to CI.    |
+--------------------------------------------------------------------------+
- Detection and Tracking: Track pipeline pass/fail rates at the individual test level using test telemetry. Flag any test that passes on a retry after failing on the initial attempt for immediate investigation.
- Quarantine: When a test is identified as flaky, immediately move it out of the blocking CI quality gate into a quarantined suite. Quarantined tests still execute to collect diagnostic data, but their failures do not block pull request merges or deployments. Every quarantined test must have an assigned owner and an explicit remediation deadline.
- Diagnosis: Examine detailed failure logs, screenshots, video captures, and network traces. Reproduce the flakiness locally by running the target test in a loop under simulated CPU and memory constraints (e.g., using
pytest-repeator running multiple parallel iterations). - Refactoring:
- Fix Timing Issues: Replace hardcoded sleep commands with explicit, conditional polling (e.g., using Playwright’s
expect(locator).toBeVisible()or Webdriver’s explicit waits) that polls until the expected condition is met or a sensible timeout expires. - Enforce Data Isolation: Ensure every test creates its own unique records (e.g., using UUIDs in usernames and account fields) and cleans up its data inside teardown fixtures.
- Virtualize Unstable Externals: Replace unpredictable third-party API calls with reliable, deterministic mocks or service virtualization containers.
- Fix Timing Issues: Replace hardcoded sleep commands with explicit, conditional polling (e.g., using Playwright’s
- Reinstatement: Require refactored tests to run successfully dozens of consecutive times in an automated stress loop before moving them out of quarantine and back into the primary blocking pipeline.
The Danger of Indiscriminate Retries
Many CI/CD tools provide automated retry settings (e.g., retry: 2), which automatically rerun any failed job or test. While retries can temporarily smooth over occasional network hiccups, using automatic retries without systematic flakiness tracking is dangerous. It masks real timing bugs, concurrency deadlocks, and race conditions, drastically increases pipeline runtimes, and allows brittle tests to multiply across the codebase unchecked.
11. Test Reporting, Observability, and Feedback
Automated testing is ineffective if developers cannot quickly interpret test results or diagnose failures. Fast, actionable, and contextual feedback ensures that engineers spend their time fixing bugs rather than decoding obscure pipeline logs.
Essential Components of Actionable Test Reporting
- Standardized Formats: Test runners must output results in structured, standardized formats (such as JUnit XML, JSON, or TAP) so that CI/CD platforms can ingest, parse, and visualize the data automatically.
- In-Context Pull Request Annotations: Rather than forcing developers to search through tens of thousands of lines of raw build console text, the pipeline should surface failure messages, stack traces, and relevant file line numbers directly within the pull request review interface.
- Diagnostic Artifact Archival: When a test fails, the pipeline should automatically capture and archive contextual debugging artifacts:
- Application and service logs filtered around the failure window.
- Detailed network request and response payloads.
- DOM snapshots, full-page screenshots, and video recordings for UI tests.
- Historical Failure Trends: Track test metrics across builds to monitor overall pass rates, identify slow-running tests, pinpoint flaky tests, and identify problematic modules across the codebase.
Distinguishing Application Bugs from Infrastructure Failures
Developers need to know immediately whether a pipeline failure stems from a defect in their code or an issue with the CI/CD infrastructure itself:
- Application Defect: Indicated by explicit assertion failures, HTTP 4xx/5xx status codes returned by application routes, or unexpected database validation errors. These point directly to logic bugs within the pull request.
- Infrastructure Failure: Indicated by runner provisioning timeouts, out-of-disk-space errors, package repository connection resets, Docker daemon crashes, or expired CI credentials. These point to pipeline configuration or infrastructure issues, not code defects.
12. Quality Gates and Release Decisions
A quality gate is an automated policy checkpoint in a CI/CD pipeline that evaluates build and test metrics against defined organizational thresholds. If an artifact meets all criteria, it is cleared for promotion to the next stage; if it fails any requirement, the pipeline halts, preventing the code from proceeding downstream.
[ Build Artifact ]
       |
       v
+--------------------------------------------------------------+
|                    EVALUATE QUALITY GATE                     |
|                                                              |
|  [x] Unit & Integration Tests: 100% Pass Rate                |
|  [x] Code Coverage on New Code: >= 80%                       |
|  [x] Critical Security Vulnerabilities (SAST/SCA): 0         |
|  [x] API Contract Compatibility: Verified                    |
|  [x] Performance Regression: p95 Latency <= Threshold        |
+--------------------------------------------------------------+
       |                                          |
   (All Pass)                                 (Any Fail)
       |                                          |
       v                                          v
[ Promote to Next Stage / Staging ]     [ Block Pipeline & Alert Team ]
Essential Quality Gate Dimensions
- Core Test Pass Rates: Enforce a strict 100% pass rate for all blocking unit, integration, and API tests. Non-passing tests must be fixed or formally quarantined; they should never be ignored.
- Critical Path Verification: Crucial business workflows (e.g., checkout, account authentication) must pass their end-to-end and regression checks without exception.
- Security Vulnerability Thresholds: Enforce zero tolerance for newly introduced “Critical” or “High” Common Vulnerability and Exposure (CVE) findings in code dependencies or container images.
- API Contract Compatibility: Ensure changes do not break schema agreements or introduce backward-incompatible modifications without appropriate API versioning.
- Code Coverage on Modified Code: Rather than mandating an arbitrary total codebase coverage figure (e.g., 90% across legacy applications), enforce coverage criteria primarily on new or modified code (e.g., requiring that 80% of newly written code paths are exercised by tests).
- Deployment Smoke Verification: Following deployment to any target environment, automated health checks and smoke tests must verify that services are healthy, responsive, and communicating before routing live traffic to the new instances.
Quality Gates vs. Release Decisions
A quality gate provides objective technical evidence regarding build stability and security, but it may not encompass the entire release decision. In continuous delivery workflows, final production releases may consider broader business factors, such as:
- Coordinating with marketing or customer support teams.
- Compliance sign-offs or external regulatory audits.
- Scheduled business maintenance windows.
- Operational readiness of external partner organizations.
In contrast, fully automated continuous deployment models rely entirely on passing automated quality gates, automatically routing traffic to new releases via canary deployments, blue-green switches, or feature flags.
13. Security Best Practices for Test Automation
Test automation infrastructure frequently possesses high-level access to source code repositories, container registries, build clusters, and internal networks. If left unsecured, CI/CD pipelines can become vulnerable vectors for credential theft, supply-chain attacks, and unauthorized system access.
Protecting Pipeline Credentials and Secrets
- No Hardcoded Secrets: Never store database passwords, API keys, or private certificates in source code or test scripts. Use dedicated secrets management platforms (such as HashiCorp Vault, AWS Secrets Manager, or native CI/CD encrypted secrets) to inject credentials into pipeline jobs at runtime as environment variables.
- Mask Secrets in Logs: Ensure all CI platform secret-masking features are enabled so that injected credentials and access tokens are automatically redacted from console outputs and build logs.
- Principle of Least Privilege: Grant CI runners and automation test accounts the minimum permissions required to perform their specific tasks. A test runner executing unit tests does not need permissions to modify production DNS records or delete container repositories.
Pipeline Infrastructure and Execution Security
- Isolate Pull Request Runs: Be cautious when running automated pipelines on pull requests submitted from public forks or untrusted branches. Untrusted contributors could alter test scripts to expose repository secrets or execute malicious code on self-hosted runners. Restrict automated secret exposure on fork-based pull requests.
- Pin Third-Party Pipeline Actions: Pin third-party CI actions, plugins, and dependencies to specific, immutable commit SHAs rather than mutable branch names (like
@mainor@v1) to protect against upstream supply-chain compromises. - Harden Build Agents: Keep CI runner operating systems, container engines, and runtime dependencies regularly patched. Ephemeral runners that are spun up dynamically and destroyed after each individual job prevent lateral movement and persistent compromise.
- Sanitize Test Reports: Ensure automated error logs, crash dumps, and stack traces do not capture sensitive internal data, authorization tokens, or customer information before archiving them as pipeline build artifacts.
14. Performance Optimization for Automated Testing
As software applications expand, test suites naturally grow larger. If left unmanaged, pipeline execution times can stretch from minutes into hours, creating long queues, delaying code reviews, and degrading team productivity. Optimizing test execution performance keeps feedback loops tight and responsive.
Practical Optimization Techniques
- Parallel Test Execution: Distribute independent test files across multiple CPU cores on a single runner, or shard test suites across multiple parallel runner nodes. Most modern frameworks (such as
pytest -n auto,JUnitparallel execution, or Playwright’s native worker threads) support parallelization natively. - Dependency and Build Caching: Leverage caching mechanisms to store package manager dependencies (e.g.,
~/.npm,~/.m2, orpipcache directories) and intermediate compilation artifacts between pipeline runs. Fetching dependencies from a local cache is significantly faster than re-downloading thousands of packages over the network on every build. - Selective Testing (Test Impact Analysis): Rather than running the entire regression test portfolio on every minor commit, inspect the Git diff to run only the tests that cover changed modules. Reserve the full, comprehensive test suite for pull request approvals or nightly builds.
- In-Memory and Ephemeral Storage: Configure integration test databases to run using in-memory configurations or memory-backed filesystems (such as
tmpfsin Docker) during CI execution. Bypassing physical disk I/O significantly accelerates database-heavy integration tests. - Prune Redundant Test Assertions: Eliminate duplicate assertions that test the exact same logic across multiple layers. If a business validation rule is comprehensively verified through dozens of millisecond-fast unit tests, avoid writing dozens of slow, heavy browser automation tests to validate the same underlying permutations.
- Optimizing Setup and Teardown Fixtures: Avoid recreating expensive test environments, database tables, or browser instances for every single test method. Where safe, group tests to share initialization fixtures across multiple read-only checks, reserving full tear-downs for tests that mutate state.
15. Measuring Test Automation Effectiveness
To ensure that test automation investments deliver genuine quality improvements, organizations should track objective operational metrics rather than relying on vanity numbers.
Key Quality and Delivery Metrics
- Pipeline Feedback Time: The total duration from a developer pushing a commit to receiving clear, actionable pass/fail test results. High-performing teams typically aim for initial pull request feedback within five to ten minutes.
- Escaped Defect Rate: The number of software defects discovered in staging or production environments compared to the total number caught by automated tests during the CI/CD pipeline. A rising escaped defect rate indicates blind spots in the automated test suites.
- Flaky Test Ratio: The percentage of tests that intermittently fail and pass on identical commits. Keeping this ratio near zero is essential for maintaining team trust in pipeline results.
- Mean Time to Diagnose (MTTD): The average time required for an engineer to review a failed pipeline run, understand the root cause from available reports and artifacts, and begin remediation.
- Defect Detection by Pipeline Stage: A metric tracking where bugs are discovered—in unit testing, integration testing, staging smoke testing, or production monitoring. Identifying defects earlier in the pipeline reduces overall remediation costs.
- Pipeline Pass/Fail Stability: The ratio of pipeline failures caused by actual code defects versus those caused by infrastructure timeouts, network glitches, or runner configuration errors.
The Limits of Vanity Metrics
Teams should avoid relying solely on superficial metrics such as total test counts or strict line coverage percentages:
- High Line Coverage Does Not Guarantee Quality: A test suite can achieve 90% code coverage simply by executing lines of code without making meaningful assertions about business outcomes or handling edge-case logic.
- Test Count Inflation: Measuring engineering productivity by the raw number of test cases authored encourages writing hundreds of trivial, low-value checks rather than addressing complex, high-risk integration flows.
16. Common Mistakes in CI/CD Test Automation
Implementing test automation within delivery pipelines is an ongoing engineering discipline. Avoiding these common organizational and technical pitfalls will help teams maintain high delivery velocity and dependable releases.
Pitfalls and Practical Solutions
- The “Automate Everything” Trap: Attempting to automate every edge case, visual layout detail, and exploratory scenario.
- Risk: Escalating maintenance costs and bloated pipeline execution times that stall releases.
- Correction: Prioritize automation for stable, high-risk, and repetitive business logic. Rely on exploratory human testing for visual nuances and novel edge cases.
- Over-Reliance on End-to-End UI Tests: Constructing an “ice cream cone” test suite dominated by heavy browser tests while neglecting unit and integration testing.
- Risk: Fragile pipelines, slow feedback cycles, frequent false positives, and difficult root-cause diagnosis.
- Correction: Follow the test pyramid principles. Push validation logic down to unit, integration, and API layers wherever possible, keeping E2E suites lean and focused on critical paths.
- Tolerating Flaky Tests: Treating intermittent pipeline failures as normal noise and simply rerunning jobs until they happen to pass.
- Risk: Eroded developer trust, leading to genuine bugs being ignored and released to production.
- Correction: Establish a strict zero-tolerance policy for flakiness. Quarantine unstable tests immediately, assign clear ownership, and fix or remove them promptly.
- Coupling Tests to Implementation Details: Writing unit tests that assert specific private methods, internal variables, or exact HTML DOM structures rather than observable inputs and outputs.
- Risk: Routine code refactoring breaks tests even when the feature works perfectly, creating high maintenance overhead.
- Correction: Write tests that assert observable behavior and public interfaces, allowing internal code to be refactored safely.
- Using Production Data Directly in Tests: Copying unmasked production databases into testing environments.
- Risk: Severe privacy violations, security vulnerabilities, potential data corruption, and regulatory non-compliance (GDPR, HIPAA).
- Correction: Use synthetic datasets, deterministic database factories, and automated schema migration seeders.
- Bypassing Failed Pipelines: Allowing developers or managers to manually override failed quality gates to hit arbitrary release deadlines.
- Risk: Completely undermines the purpose of the pipeline, allowing defects and vulnerabilities into production.
- Correction: Require all blocking tests to pass. If an issue is verified as a false positive, update or quarantine the test through a proper code review rather than bypassing the gate.
- Neglecting Test Maintenance Ownership: Treating automated test suites as an afterthought without designated team ownership or refactoring time.
- Risk: Slow, decaying test suites that gradually fall out of sync with application changes.
- Correction: Treat test code with the same engineering rigor as production code. Review tests in pull requests, allocate time for technical debt remediation, and track suite performance continuously.
17. Illustrative Case Study: Modernizing a Delivery Pipeline
The following scenario is a hypothetical, illustrative case study designed to demonstrate how an engineering team can systematically modernize its testing workflows.
Initial State and Operational Challenges
A mid-sized software company maintaining an e-commerce platform released updates on an alternating bi-weekly schedule. Every release required a grueling, three-day “code freeze” during which three dedicated QA engineers manually executed spreadsheets containing over 400 manual regression test steps.
Despite this time-consuming manual effort, regressions regularly slipped into production. Hotfixes were common, and developers frequently waited over a week to discover that a change made days earlier had broken an unrelated inventory calculation. When developers attempted to introduce automated tests, they wrote large Selenium UI scripts that frequently broke whenever marketing adjusted page styling, causing team members to lose faith in the pipeline results.
Phased Transformation Strategy
The engineering organization adopted an incremental approach to modernize its delivery pipeline over a six-month period:
[ Phase 1: Baseline & Shift-Left ]
  * Stabilize core business logic with fast unit tests.
  * Integrate linters, formatters, and secrets scanning on PRs.
  * Feedback: Reduced from days to under 3 minutes.
                 |
                 v
[ Phase 2: Service Layer & Ephemeral Containers ]
  * Introduce API tests using real schemas via ephemeral test containers.
  * Validate database migrations and checkout transactions.
  * Result: 85% of regressions caught before touching a browser.
                 |
                 v
[ Phase 3: Lean E2E & Browser Modernization ]
  * Replace brittle Selenium tests with Playwright.
  * Automate only the top 10 core customer journeys.
  * Isolate tests with dynamic test data fixtures.
                 |
                 v
[ Phase 4: Staged Quality Gates & Canary Releases ]
  * Enforce 100% pass rates on unit/API tests.
  * Automated staging deployments with smoke verification.
  * Quarantine flaky tests immediately under strict SLAs.
- Phase 1: Establishing Fast Feedback: The team started by focusing on the base of the test pyramid. They integrated automated linting, static security scanning, and unit tests directly into pull request workflows. They established a hard rule: unit tests had to execute entirely in memory without network or database dependencies, returning results to developers in under three minutes.
- Phase 2: Service-Layer API Automation: Next, the team targeted the brittle UI tests. Instead of driving an entire browser to test business calculations, they wrote API tests that directly validated endpoint responses, status codes, and database transactions. They adopted lightweight, containerized PostgreSQL instances inside the CI runners to run database migrations and repository tests against real schemas.
- Phase 3: Streamlined End-to-End Validation: The team audited their 400-step manual regression checklist and identified the core 10 customer journeys that accounted for 90% of business revenue (e.g., user login, product search, cart checkout, and payment processing). They automated only these essential flows using Playwright, leveraging resilient accessibility locators (ARIA roles) and dynamic test data generation rather than static, shared accounts.
- Phase 4: Structured Quality Gates: Finally, the team configured their CI/CD platform to enforce structured quality gates. Pull requests required passing unit, integration, and security checks before merging. Merges to the primary branch triggered automated deployments to an ephemeral staging environment, where smoke tests and core E2E suites executed automatically.
Outcomes and Retrospective Lessons
- Elimination of Release Freezes: The three-day manual regression freeze was replaced with an automated 20-minute CI/CD pipeline, allowing the team to transition from bi-weekly releases to multiple production updates per day.
- Faster Remediation: Developers identified defects within minutes of submitting code, dramatically reducing the time spent tracking down regressions.
- Empowered QA Focus: Freed from repetitive manual spreadsheet testing, QA engineers shifted their focus to security audits, performance testing, and user-centric exploratory sessions that automation cannot replicate.
18. Illustrative Test Automation Maturity Model
Organizations adopt automated testing in stages as their technical practices and tooling evolve. The following four-level framework illustrates how teams typically progress from manual testing to a mature, continuously improving quality engineering workflow.
+-----------------------------------------------------------------------------------+
| LEVEL 4: CONTINUOUSLY OPTIMIZED                                                   |
| - Dynamic, risk-based test selection; deep test and pipeline observability.        |
| - Comprehensive shift-left and shift-right testing with automated canary checks. |
+-----------------------------------------------------------------------------------+
                                         ^
                                         |
+-----------------------------------------------------------------------------------+
| LEVEL 3: INTEGRATED & RISK-BASED                                                  |
| - Multi-layered test portfolio (Unit, Integration, API, Lean E2E).                |
| - Ephemeral environments; automated quality gates; systematic flaky test triage.  |
+-----------------------------------------------------------------------------------+
                                         ^
                                         |
+-----------------------------------------------------------------------------------+
| LEVEL 2: BASIC AUTOMATION                                                         |
| - Unit tests run in CI; some automated UI or integration scripts exist.           |
| - Fragile shared environments; long execution times; frequent manual overrides.   |
+-----------------------------------------------------------------------------------+
                                         ^
                                         |
+-----------------------------------------------------------------------------------+
| LEVEL 1: MANUAL & REACTIVE                                                        |
| - Releases depend entirely on manual verification; no CI test enforcement.        |
| - Long regression cycles; defects routinely discovered late or in production.     |
+-----------------------------------------------------------------------------------+
Level 1: Manual and Reactive
- Characteristics: Testing is largely manual, managed via spreadsheets or ticketing systems. The CI/CD pipeline, if one exists, merely compiles code and builds artifacts without executing tests.
- Limitations: Long delivery cycles, late defect discovery, developer feedback delays of days or weeks, and high operational stress during deployments.
- Next Steps: Introduce automated linting, static code analysis, and a small foundational suite of fast unit tests on code commits.
Level 2: Basic Automation
- Characteristics: Unit tests run consistently in CI, and some automated integration or browser tests exist. However, tests are often slow, tightly coupled to implementation details, and run against shared, mutable development environments.
- Limitations: Pipelines frequently fail due to environmental flakiness and data collisions. Developers routinely bypass or ignore test failures to meet release deadlines.
- Next Steps: Separate fast unit tests from slower integration suites; implement containerized, ephemeral dependencies; and enforce strict pass/fail rules on pull request gates.
Level 3: Integrated and Risk-Based
- Characteristics: A balanced test pyramid is integrated across distinct pipeline stages. Unit, integration, API, security, and focused end-to-end suites execute based on clear triggers. Ephemeral environments isolate test runs, and flaky tests are systematically quarantined and triaged.
- Limitations: Slower pipeline stages can occasionally congest delivery queues during peak hours, and test selection remains largely static across different types of changes.
- Next Steps: Implement test impact analysis, parallelize test suites across distributed workers, and integrate automated deployment smoke tests with rollback mechanics.
Level 4: Continuously Optimized
- Characteristics: Automated testing is treated as a strategic engineering discipline. Pipelines use dynamic test selection to run only tests relevant to modified code paths. Ephemeral environments spin up and tear down on demand, and quality gates enforce security, performance, and stability criteria. Telemetry from production canaries feeds back into test suites to continuously improve coverage.
- Limitations: Requires ongoing engineering investment, cross-functional discipline, and continuous platform maintenance to prevent configuration drift.
- Next Steps: Continue refining performance thresholds, expand consumer-driven contract testing across distributed services, and optimize runner infrastructure costs.
19. Emerging Trends in CI/CD Test Automation
Test automation continues to evolve alongside advances in cloud-native platforms, containerization, and intelligent developer tooling. Understanding these emerging trends helps teams design forward-looking testing architectures.
- Intelligent Test Selection and Predictive Execution: Modern testing tools analyze source code changes, historical failure patterns, and code coverage maps to predictively execute only the specific subset of tests relevant to a given pull request. This significantly accelerates pipeline feedback while preserving test safety.
- AI-Assisted Test Generation: Machine learning models are increasingly used to generate boilerplate unit tests, identify unhandled edge cases, and propose assertions based on functional code analysis. While promising, AI-generated tests still require human code review, validation, and maintenance to ensure they assert meaningful business behavior rather than simply mirroring implementation bugs.
- Self-Healing Test Automation: Modern end-to-end frameworks are incorporating intelligent locator strategies that adapt when minor UI layout adjustments occur. If a specific button ID or CSS class changes, the runner uses surrounding semantic attributes and accessibility labels to locate the target element, reducing false-positive failures.
- Consumer-Driven Contract Testing at Scale: In complex microservices and distributed cloud environments, running massive end-to-end integration environments is often impractical. Consumer-driven contract testing (e.g., using frameworks like Pact) is increasingly replacing complex multi-service staging environments by verifying service compatibility independently at build time.
- Shift-Right Testing and Production Observability: Quality engineering is expanding beyond pre-release pipelines into production environments. Techniques such as synthetic user monitoring, automated canary analysis, chaos engineering, and feature flag management allow teams to safely test and observe new code behaviors in production under real-world traffic conditions.
20. Practical CI/CD Test Automation Checklist
Engineering teams can use the following checklist to evaluate, implement, and refine their automated testing workflows across their delivery pipelines.
Strategy and Architecture
- Quality objectives, business risks, and critical user journeys are explicitly documented.
- The testing portfolio aligns with the test pyramid heuristic (robust unit/API layers, focused E2E suites).
- Clear boundaries are established between unit, integration, and end-to-end tests.
- Fast, deterministic tests are prioritized over slow, high-maintenance checks.
Frameworks and Tooling
- Test frameworks are standardized and natively supported by the project’s language ecosystem.
- Test runners support parallel execution, parameterization, and headless execution.
- Test runners output structured reports (e.g., JUnit XML) for pipeline ingestion.
- Test dependencies are pinned, maintained, and cached across pipeline runs.
Test Environment and Data
- Test environments are automated, reproducible, and isolated from external interference.
- Ephemeral containers are used for running integration dependencies (databases, caches, brokers).
- Tests generate their own unique test data at runtime using factories or APIs.
- Production databases are never copied directly into test environments without masking and sanitization.
- External third-party dependencies are simulated using reliable test doubles or virtualization tools.
Pipeline Configuration and Quality Gates
- [ ] The pipeline enforces a “fail-fast” execution order: static checks and unit tests run first.
- [ ] Quality gates enforce a 100% pass rate on all blocking test suites.
- [ ] Automated security scans (SAST, SCA, and secrets detection) are integrated into pull requests.
- [ ] Merges and deployments are blocked when critical quality gates fail.
- [ ] Deployment smoke tests and readiness checks run automatically following promotions.
Reporting, Maintenance, and Security
- Diagnostic artifacts (logs, traces, screenshots) are archived and accessible for failed runs.
- Failures surface actionable error messages and file annotations in pull request interfaces.
- Flaky tests are quarantined immediately, assigned an owner, and triaged under strict deadlines.
- Sensitive credentials, tokens, and secrets are injected via secure managers and masked in logs.
- Pipeline metrics (execution time, pass rates, escaped defects) are regularly tracked and reviewed.
21. Skills and Learning Resources for Continuous Testing
Building and maintaining dependable automated testing pipelines requires a blend of software development, quality engineering, systems administration, and DevOps expertise.
Core Competencies for Quality Engineering in DevOps
- Software Development and Scripting: Writing clean, maintainable, and modular test code using object-oriented, functional, or behavior-driven patterns.
- Testing Architecture and Methodologies: Mastering unit, integration, API, security, performance, and regression testing principles and design patterns.
- CI/CD Pipeline Orchestration: Defining declarative pipelines, configuring multi-stage workflows, managing caching layers, and coordinating parallel execution in platforms like GitHub Actions, GitLab CI/CD, Jenkins, or Azure Pipelines.
- Containerization and Infrastructure as Code: Using Docker, Docker Compose, Kubernetes, and Terraform to provision reproducible, ephemeral test environments on demand.
- Security and DevSecOps Practices: Integrating static and dynamic security scanning, secrets detection, software composition analysis, and least-privilege access controls throughout delivery workflows.
- Observability and Telemetry: Configuring structured logging, test reporting dashboards, metric tracking, and synthetic production monitoring.
For engineers, quality specialists, and technical teams looking to develop practical skills across continuous integration, pipeline architecture, and cloud-native automation, exploring training programs and structured learning platforms like DevOpsSchool provides hands-on opportunities to master modern DevOps and delivery practices.
22. Frequently Asked Questions
1. What is test automation in CI/CD?
Test automation in CI/CD is the practice of running software verification suites programmatically within a continuous integration and continuous delivery pipeline. Whenever code is committed, opened in a pull request, or merged, the pipeline automatically executes builds and tests to evaluate application correctness, stability, and release readiness without human intervention.
2. Why should testing be automated in a CI/CD pipeline?
Automating tests provides rapid feedback to developers within minutes of making a change, catches defects early before they reach downstream environments, reduces repetitive manual testing effort, ensures consistent release validation, and enables teams to deploy updates safely and frequently.
3. Which tests should run first in a CI/CD pipeline?
Fast, lightweight, and deterministic tests should always execute first. This includes source code linters, formatting checks, secrets detection, static security analysis, and isolated unit tests. Slower tests—such as database integration, API contract, and browser-driven end-to-end tests—should run only after the code passes these initial validation stages.
4. What is the difference between unit testing and integration testing?
Unit testing validates the smallest units of application logic (such as individual functions or methods) in complete isolation, replacing external dependencies with test doubles (mocks or stubs). Integration testing verifies that distinct components, services, database queries, and external APIs interact correctly across network, filesystem, or database boundaries.
5. Should end-to-end (E2E) tests run on every code commit?
Generally, no. Exhaustive end-to-end suites are slow, resource-intensive, and susceptible to environment flakiness. Running them on every commit can create pipeline bottlenecks. Instead, teams should run fast unit and integration tests on every commit and pull request, reserving a lean suite of critical E2E tests for post-merge, staging deployments, or nightly pre-release runs.
6. Which tools are commonly used for CI/CD test automation?
Common tools include xUnit frameworks for unit testing (JUnit, pytest, Jest), Playwright and Cypress for browser automation, REST Assured and Newman for API testing, k6 for load testing, Trivy and SonarQube for security and code quality, and GitHub Actions, GitLab CI/CD, Jenkins, and Azure Pipelines for pipeline orchestration.
7. How do I integrate automated tests into a CI/CD pipeline?
You integrate tests by declaring them as execution steps within your CI/CD configuration file (such as a GitHub Actions YAML or Jenkinsfile). The pipeline checks out the repository, prepares the runtime environment, installs dependencies, runs the test runner via command-line instructions (e.g., pytest or mvn test), parses the resulting test reports, and evaluates pass/fail status codes.
8. What is the test automation pyramid?
The test automation pyramid is a design model that recommends maintaining a broad foundation of fast, inexpensive, and isolated unit tests, a moderate layer of integration and API tests, and a smaller, highly focused apex of end-to-end UI tests. This structure ensures comprehensive coverage while keeping pipeline execution fast and maintainable.
9. How can teams reduce flaky tests?
Teams can minimize flakiness by eliminating arbitrary sleep statements and using explicit conditional waiting, ensuring tests create and clean up their own isolated test data, replacing unpredictable third-party dependencies with mocks or service virtualization, running integration tests in isolated ephemeral containers, and immediately quarantining unstable tests until fixed.
10. How should test data be managed in CI/CD?
Test data should be generated dynamically at runtime using test fixtures or API calls so that tests do not depend on pre-existing shared state. For integration tests, apply database migrations and seed scripts to fresh, ephemeral database containers. Never copy unmasked, sensitive production databases into test environments.
11. What are quality gates in automated testing?
Quality gates are automated policy checkpoints in a CI/CD pipeline that evaluate test outcomes against defined criteria (such as 100% test pass rates, code coverage thresholds, and zero critical security vulnerabilities). If the build satisfies these criteria, it is cleared for promotion; if it fails, the pipeline halts immediately.
12. How can teams speed up slow test pipelines?
Teams can accelerate pipelines by running independent test files in parallel across multiple cores or distributed runner nodes, caching package manager dependencies, running in-memory or ephemeral databases (e.g., using tmpfs), using test impact analysis to execute only tests relevant to modified code, and moving slow, broad suites to scheduled nightly runs.
13. How does automated testing support DevSecOps?
Automated testing supports DevSecOps by “shifting left” security verification into the early stages of delivery. Pipelines automatically execute static application security testing (SAST), software composition analysis (SCA), secrets detection, and infrastructure-as-code linting on pull requests, identifying vulnerabilities before software is deployed.
14. How can test automation effectiveness be measured?
Key metrics include pipeline feedback time, escaped defect rates in production, the percentage of flaky tests, mean time to diagnose failures, and test pass/fail trends over time. Teams should focus on actionable metrics that reflect delivery speed and system stability rather than vanity metrics like raw test counts or total code coverage percentages.
15. Does automated testing eliminate the need for manual testing?
No. Automated testing handles repetitive, deterministic, and programmatic checks, freeing human testers to perform high-value exploratory testing, evaluate user experience and visual design, conduct security audits, and assess complex business scenarios that automated scripts cannot effectively evaluate.
23. Conclusion
Automating testing within a CI/CD pipeline strengthens modern software delivery by replacing slow, error-prone manual verification with fast, repeatable feedback and dependable release decisions. True pipeline reliability does not stem from accumulating an unsustainable volume of brittle scripts, but from strategically aligning tests with the test pyramid, provisioning clean and ephemeral environments, eliminating flakiness, and enforcing objective quality gates. By starting with critical business workflows, automating high-value checks first, and expanding skills through platforms like DevOpsSchool , teams can systematically scale continuous testing to deliver secure, resilient software with confidence.